Tutorial · curl, Node.js, Python
How to scrape X (Twitter) transcripts with Python, Node.js or curl (2026)
A walkthrough for GET /v1/twitter/tweets/transcript, with the same request in curl, Node.js and Python. Copy the snippet, run it, then read the JSON.
GET /v1/twitter/tweets/transcript · 1 credit
In this tutorial
You'll pull a X (Twitter) transcript from a public video URL and see the text you get back.
Typical job: a news desk with video posts from an alert feed. Read the spoken text from data.transcript, a plain string. Check lookupStatus first: transcript is null when no speech was found or the video is too long to transcribe, which isn't a failed request. x.com and twitter.com links both work.
Step 1
Get ready
Create a Social Fetch API key, then get curl, Node.js or Python ready. New accounts include 100 free credits.
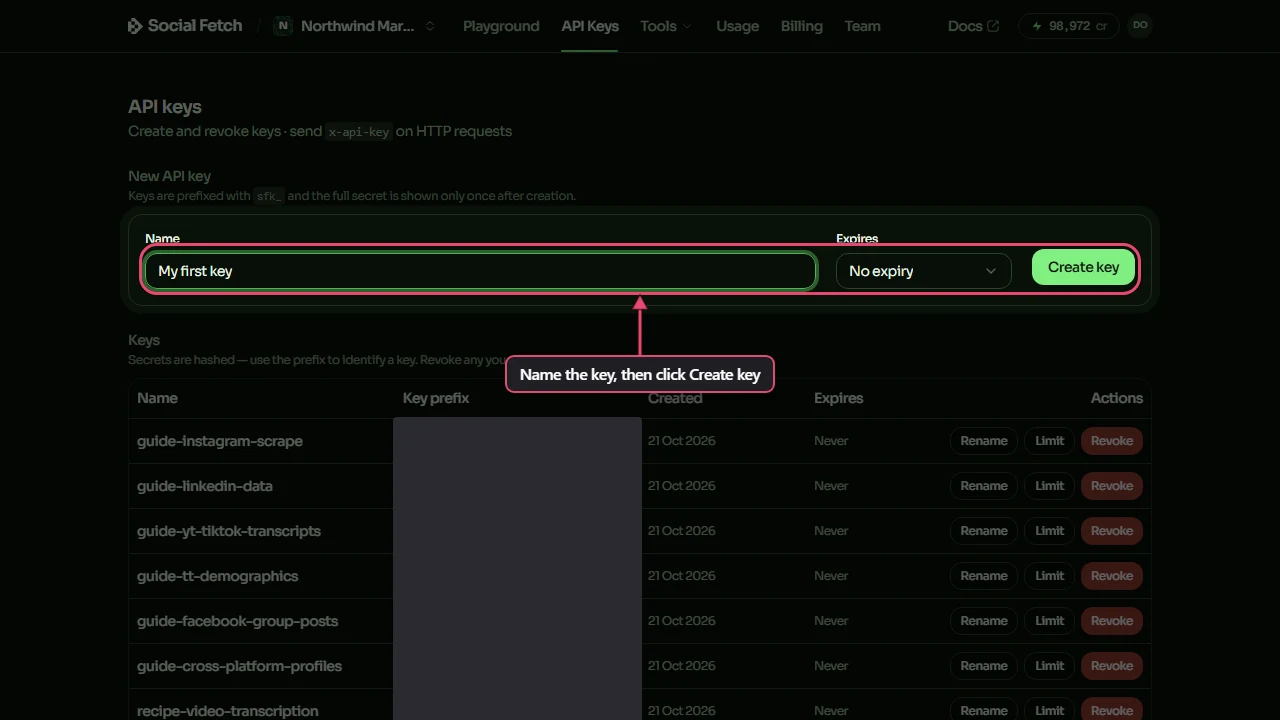
API key. Create a Social Fetch account, open API Keys and create a key. New accounts include 100 free credits.
curl. Any shell with curl. Set SOCIALFETCH_API_KEY to your key (export SOCIALFETCH_API_KEY=sfk_…) before you run the sample.
Node.js. Node 18 or later, which has fetch built in. Save the sample as an .mjs file so top-level await works, and set SOCIALFETCH_API_KEY to your key.
Python. Python 3 with requests installed (pip install requests). Set SOCIALFETCH_API_KEY to your key.
When you're done, SOCIALFETCH_API_KEY is set in your shell.
Step 2
Make the request
Pick curl, Node.js or Python, copy the sample and run it. It calls GET /v1/twitter/tweets/transcript with your key in the x-api-key header, using this example: /v1/twitter/tweets/transcript?url=https%3A%2F%2Fx.com%2FNASA%2Fstatus%2F2112560723603632217.
Each sample prints the JSON response with data and meta. On an error status, the Python sample stops at raise_for_status() and the Node.js sample throws with the error body, because it checks response.ok first. curl prints the error JSON; add --fail-with-body to make it exit non-zero.
Step 3
Read the response
The response is JSON with two parts: data holds the transcripts and meta holds creditsCharged and requestId. The sample below is a trimmed copy of a real response; the endpoint page lists every field. Credits are charged on completed lookups, not on failed requests.
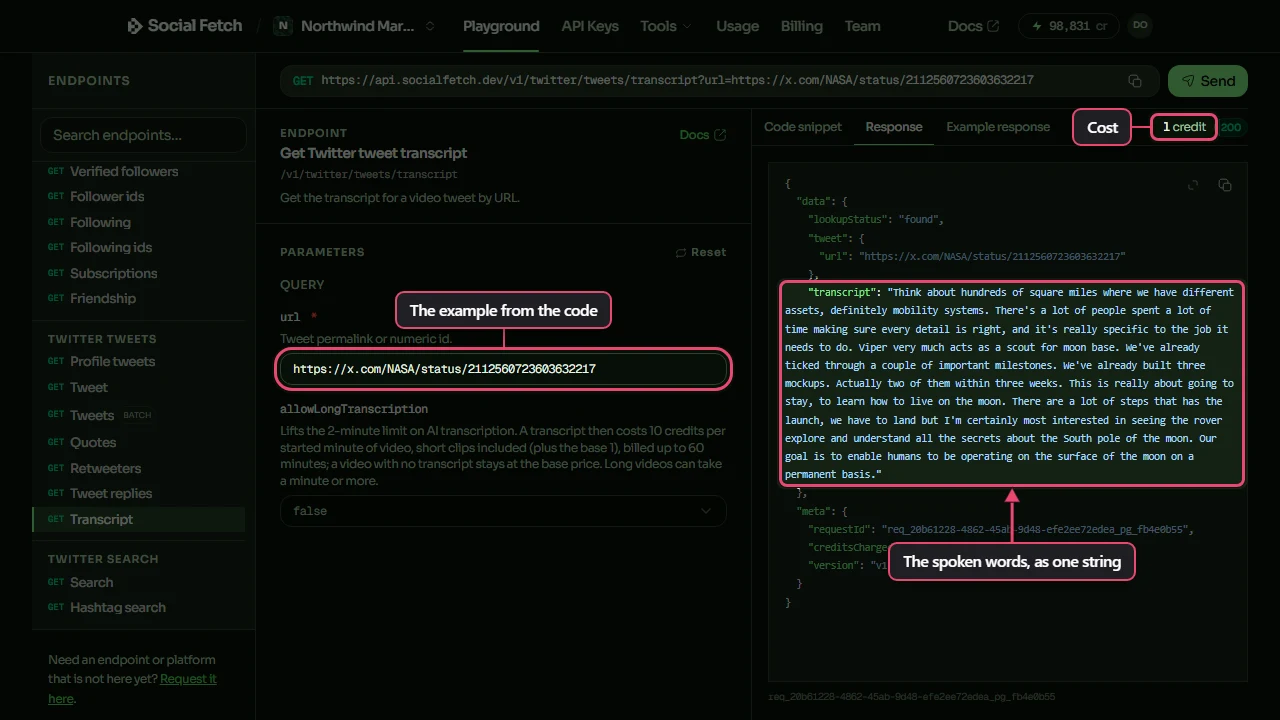
Check data.lookupStatus first when the response has one. Keep meta.requestId in case a row looks wrong.
Watch out
found with a null transcript is a normal answer, not a reason to retry. Posts without a video have nothing to transcribe. Videos over 2 minutes need allowLongTranscription=true, at 10 credits per started minute.
Step 4
You finished
The Playground, the docs and your code all call the same endpoint at the same price. Pick a next step below.
FAQ
Common questions
Do I need an official X (Twitter) developer account?
No. Social Fetch authenticates with your Social Fetch API key. You call GET /v1/twitter/tweets/transcript and we handle the lookup. You still need to follow each platform's terms for how you use public data.
What does the X (Twitter) transcripts endpoint return?
JSON with two parts: data holds the transcripts and meta holds creditsCharged and requestId. The endpoint page and the API docs describe every field.
Does a found X tweet transcript lookup always return spoken text?
No. found means the post was read. data.transcript can still be null when no speech is detected, the video is longer than supported, or transcription isn't available. A completed request is still charged.
Do x.com and twitter.com status URLs both work?
Yes. Pass either as the url query parameter, or just the post's numeric id. Check lookupStatus, then read data.transcript, which is a plain string when there is one.
How much does a successful request cost?
1 credit. +10 credits per started minute of transcribed video, up to 60 minutes (allowLongTranscription). Max 601 credits. Failed requests are free.
Is this okay for production?
Yes. It's the same API the Playground and the docs use: typed errors, a requestId on every response, and credits charged only on completed lookups. New accounts get 100 free credits.
Any curl-specific tips for this request?
Yes. Pass the key with -H "x-api-key: $SOCIALFETCH_API_KEY", and wrap the full URL in double quotes so the shell doesn't split it at the & between query parameters. -sS hides the progress meter but still shows connection errors. curl doesn't treat an HTTP error status as a failure, so read the error JSON it prints, or add --fail-with-body.
Any Node.js-specific tips for this request?
Yes. Native fetch doesn't throw on 4xx or 5xx responses, so check response.ok (or status) before parsing JSON. Keep meta.requestId from the body in case you need support with a row.
Any Python-specific tips for this request?
Yes. Call response.raise_for_status() before response.json(), set a timeout on requests.get, and keep response.json()["meta"]["requestId"] when a row looks wrong.
Related