Find public posts about a product, then narrow the search to a community. This walkthrough searches for switching from notion, reads the results in the Playground, and repeats the request from code. It uses Social Fetch's API, with its own key and credit balance.
You'll need a Social Fetch account and credits. Open API keys, enter a name for your script, click Create key, and copy the key from Save your API key before clicking Done. Keep it in your environment as SOCIALFETCH_API_KEY; don't put it in browser code or a public repository. See Quickstart for the full setup.
Choose a search endpoint
| Endpoint | What it searches | SDK method |
|---|---|---|
GET /v1/reddit/search | Public posts across Reddit, using a required query | client.reddit.search() |
GET /v1/reddit/subreddits/search | Posts inside the required subreddit, with an optional query | client.reddit.searchSubreddit() |
The second endpoint searches posts within a community. To decide which communities to investigate, read the subreddit names in global results. To browse a known community's feed, use List subreddit posts.
Try a global search
- Open the Playground.
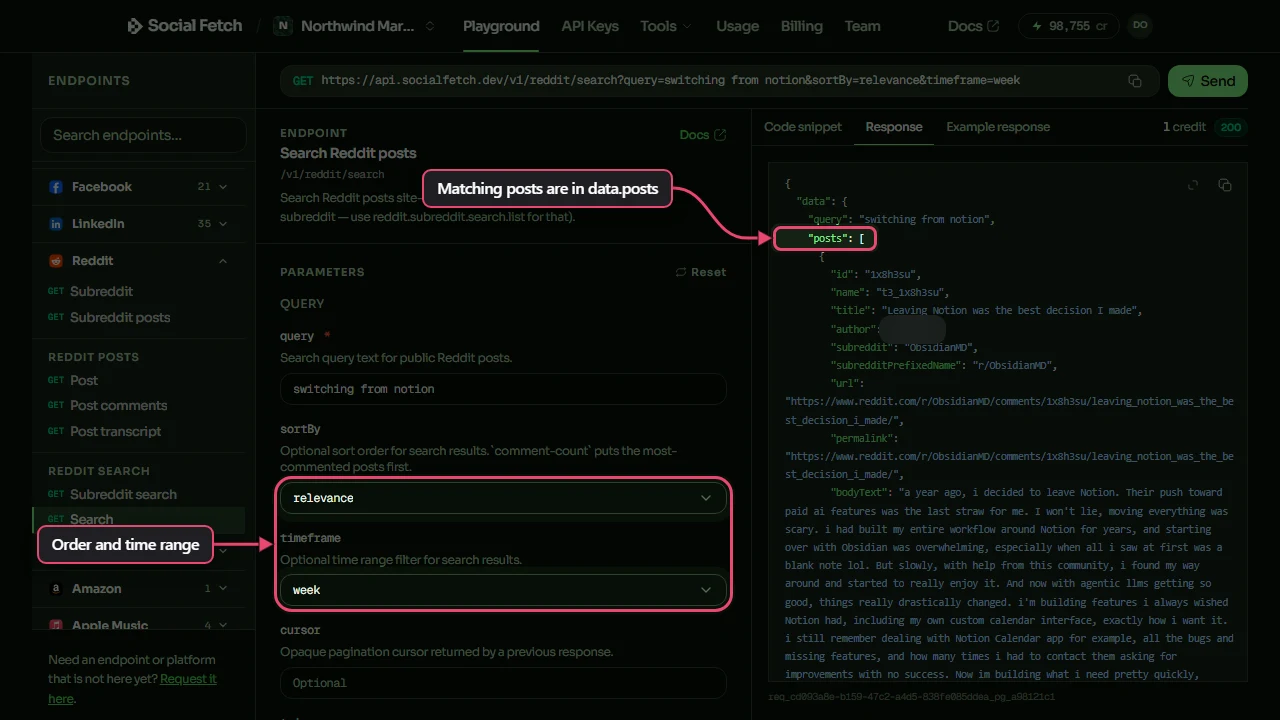
- Select Reddit's Search endpoint,
GET /v1/reddit/search. - Enter
switching from notionin query. - Set sortBy to
relevanceand timeframe toweek. - Click Send and read Response. Example response is a sample response, not the result of your request.
To send the same request from a terminal, set SOCIALFETCH_API_KEY first. In a Bash shell:
In PowerShell, use $env:SOCIALFETCH_API_KEY and curl.exe when adapting this command. --data-urlencode preserves spaces and punctuation in query values.
Search words can match loosely. Read each title and body before treating it as evidence that someone switched products. A phrase in the query doesn't guarantee an exact phrase match or complete coverage of Reddit.
Read the results and charge
The JSON has two top-level objects: data holds the search results; meta describes this request and its charge.
| Field | Meaning |
|---|---|
data.posts | Posts on this page |
data.totalResults | Number of posts on this page, not all matching posts on Reddit |
data.page.hasMore | Whether another page is available |
data.page.nextCursor | Opaque value to send as cursor on the next request |
meta.creditsCharged | Credits charged for this request |
meta.requestId | Request identifier to keep for support |
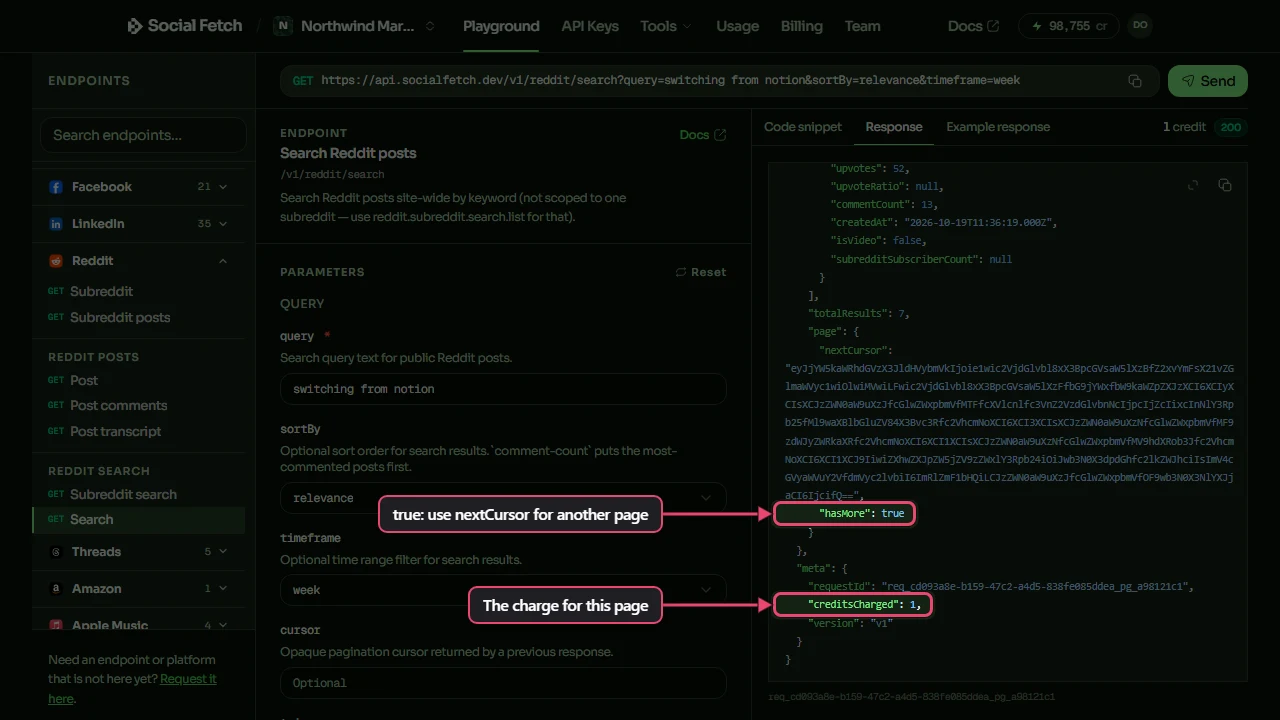
Global search posts contain id, title, bodyText, subreddit, url, permalink, score, commentCount and createdAt. Many fields can be null: a missing body doesn't mean the search failed, and a null comment count isn't zero. Keep null values when storing results. Use id to deduplicate overlapping searches; use the post's url, when present, to read its comments.
Each completed search page costs 1 credit, including an empty page. Clicking Send again or requesting the next page makes another billable request. Removing duplicate posts afterwards doesn't refund those requests. lookup_failed and 503 temporarily_unavailable responses aren't charged. See Credits and Pricing for credit purchases and plans.
Search inside a subreddit
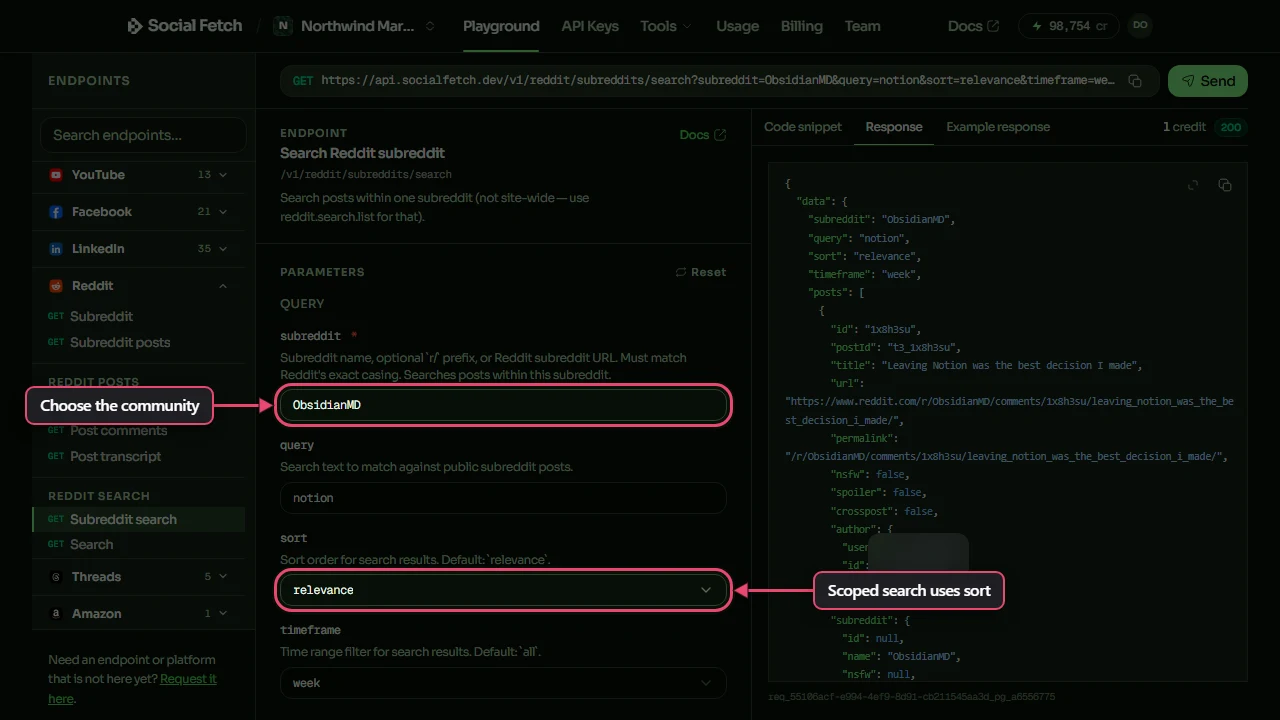
- Select
GET /v1/reddit/subreddits/searchin the Playground. - Enter
ObsidianMDin subreddit andnotionin query. - Set sort to
relevanceand timeframe toweek. - Click Send and read Response.
The response fields differ
Global search uses bodyText, a string subreddit, and commentCount.
Subreddit search uses text, an object subreddit with name, and
metrics.comments. Its author is an object with username and id, or
null. Use the schema for the endpoint you called.
Use the exact subreddit casing from its URL, such as ObsidianMD. Social Fetch's subreddit lookups are case-sensitive. Scoped search defaults to sort=relevance and timeframe=all when omitted. You can omit query to search without keyword text; an empty string is invalid.
Choose filters and sorting
| Parameter | Global search | Subreddit search |
|---|---|---|
query | Required, 1-512 characters after trimming | Optional, 1-512 characters when provided |
| Community | Across Reddit | Required subreddit |
| Order | sortBy: relevance, new, top, comment-count | sort: relevance, hot, top, new, comments |
timeframe | all, day, week, month, year | all, hour, day, week, month, year |
cursor | Previous page's nextCursor | Previous page's nextCursor |
Use relevance to explore a topic, new for recent posts, top for score order, or comment-count (comments in scoped search) to find busy discussions. Set filters explicitly when repeating a search. Neither search exposes a page-size limit parameter. The global reference also documents the optional trim flag for requesting a smaller response where available.
Paginate with the SDK
Keep the endpoint, query, sort and timeframe unchanged when passing a cursor. Treat cursors as opaque strings: don't decode, edit or invent them. Stop when hasMore is false, even if the last page has posts. An empty page alone isn't an end condition when hasMore is true.
Install the SDK and a TypeScript runner in your own project:
Save this as reddit-search.mts. The .mts ending allows the top-level await. It reads at most two global search pages (up to 2 credits), deduplicates posts by ID and preserves missing values. It writes request IDs and errors to stderr, with JSON results on stdout.
Run it with the same environment variable:
If there are more than two pages, this script intentionally returns a partial result. Increase the page budget only after deciding how many credits to spend. A missing or repeated cursor stops the script with an error instead of looping. For a scoped loop, call searchSubreddit() with subreddit and sort, and change the field mapping as described above.
Troubleshooting
| Symptom | What to check |
|---|---|
unauthorized (401) | Set a valid Social Fetch key in x-api-key. A Reddit OAuth token isn't a Social Fetch key. |
insufficient_credits (402) | Check the workspace balance. Each additional page needs another credit. |
bad_request (400) | Use the endpoint's exact parameter names and enum values. Global search requires query; scoped search requires subreddit. |
Empty posts | Check the query, community casing and timeframe. Widen one filter, then review the new response. A completed empty search is still charged. |
| Missing body, counts or thumbnails | These fields can be null. Scoped thumbnails are usually null. Use the post URL to inspect the discussion. |
lookup_failed | Keep the error's requestId; try again later or contact support if it persists. |
temporarily_unavailable (503) | Honour Retry-After when present before retrying. Authenticated searches have no per-minute quota, but capacity failures can still happen. |
Raw HTTP errors use error.code, error.message and error.requestId. The SDK returns { ok: false, error }; check ok before reading value. Don't treat an error or a budget-limited run as a complete research result. If needed, contact support with the request ID.
Social Fetch searches public data using its own credentials. Reddit's official Data API is a separate service with its own authentication and access terms. See How to get a Reddit API key if you're deciding between them. These search results are a changing set of available matches, not a complete archive or a measurement of how common an opinion is.