Search for discussions about a product, narrow the search to relevant communities, then read selected comments before writing research notes. This guide uses Notion as an example. Replace it with your product or competitor.
You'll need a Social Fetch account with credits. The Playground lets you try requests without code. For the batch script, create an API key and follow the SDK setup. Keep the key in your environment as SOCIALFETCH_API_KEY.
Build the query matrix
Write the question you want to answer before searching. For example: "What problems do people describe when considering a move from Notion?" Try each phrase as a separate query so you can record which search found a thread.
| Question | Example query | What to check in the discussion |
|---|---|---|
| Why consider another product? | notion alternative | Is the author comparing products or promoting one? |
| What prompted a move? | switching from notion | Did someone actually switch, or only ask about it? |
| What feels slow? | notion too slow | Which task, device or workspace caused the problem? |
| What is missing? | wish notion had | Is the feature absent, or did someone suggest a workaround? |
Search can match loosely. Read the returned titles and body text before treating a result as a product mention. A name check removes some irrelevant matches; it cannot decide whether a complaint is accurate.
Search Reddit
- Open Reddit Search in the Playground.
- Set query to
switching from notion. - Set sortBy to
relevanceand timeframe toweek. - Click Send and open Response.
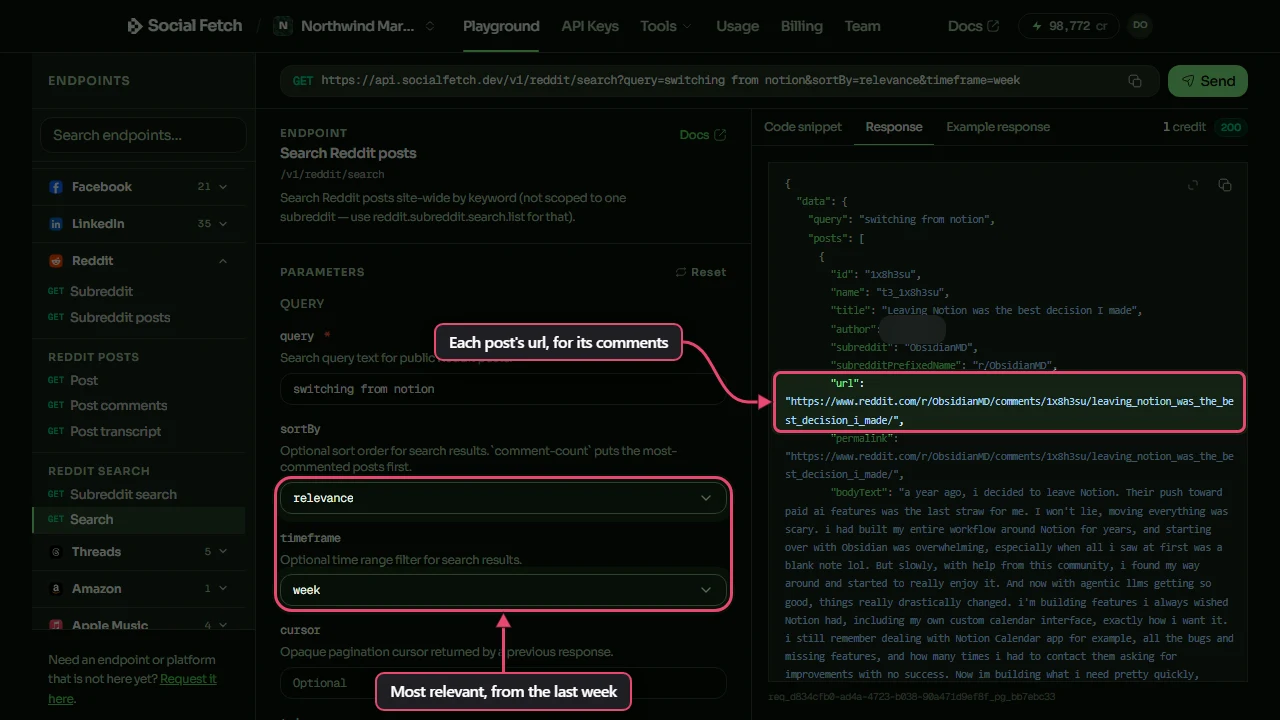
GET /v1/reddit/search returns posts in data.posts. Each post has title, bodyText, subreddit, score, commentCount, createdAt and url. Some values can be null.
| Parameter | Accepted values | Use |
|---|---|---|
sortBy | relevance, new, top, comment-count | Choose relevant, recent, highest-scoring or most-commented matches |
timeframe | day, week, month, year, all | Limit the search window |
cursor | Returned data.page.nextCursor | Continue the same search |
data.totalResults counts posts in this response. It is not the total number of matches across Reddit. Check data.page.hasMore before fetching another page. See the search reference.
Scope to subreddits
Read post.subreddit from the global results and choose communities relevant to the question. Search inside a community to check its discussions separately.
- Open Subreddit Search.
- Set subreddit to
ObsidianMDand query tonotion. - Set sort to
relevanceand timeframe toweek. - Click Send and open Response.
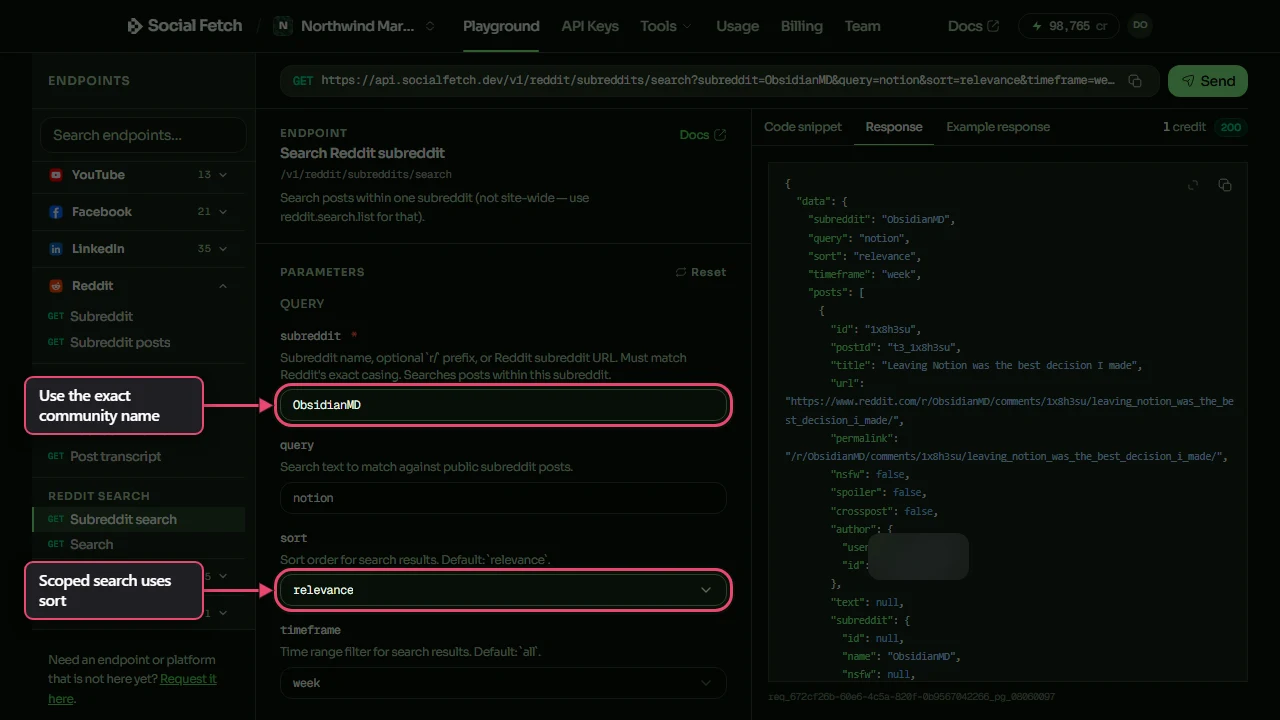
Keep the exact subreddit casing
Social Fetch's subreddit lookups are case-sensitive. Copy ObsidianMD from the community URL rather than changing it to obsidianmd. A completed not_found lookup still costs a credit.
The scoped search accepts sort values relevance, hot, top, new, comments, and timeframe values all, year, month, week, day, hour. Its result shape differs from global search:
| Value to store | Global search | Scoped search |
|---|---|---|
| Body | post.bodyText | Not returned (post.text is null) |
| Score or votes | post.score | post.metrics.votes |
| Comment count | post.commentCount | post.metrics.comments |
| Community | post.subreddit | post.subreddit?.name |
| Date | post.createdAt | post.createdAt |
For bodies from one community, use global search with the community in the query, such as subreddit:ObsidianMD notion.
To browse without keywords, use subreddit posts, for example client.reddit.listSubredditPosts({ subreddit: "ObsidianMD", sort: "new" }). On that feed endpoint, supply timeframe only with sort: "top". Feed posts use text, publishedAt and metrics.commentCount.
Pull comment threads
Choose a discussion whose title and body address your question. A larger commentCount gives you more discussion to inspect; it does not measure how common a problem is among customers.
- Copy a post's
urlfrom the search response. - Open Post Comments.
- Paste the post URL into url.
- Click Send and read Response.
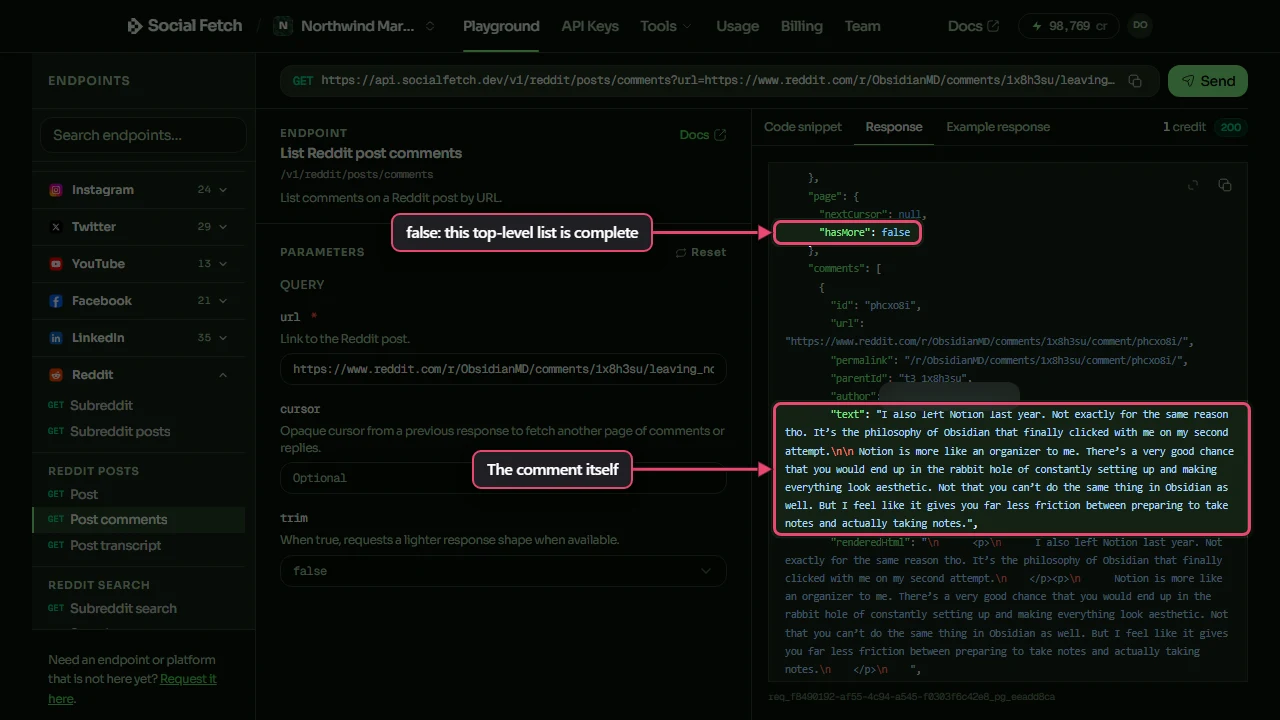
In the SDK, call client.reddit.listPostComments({ url: postUrl }). Check result.ok, then result.value.data.lookupStatus. A found response contains data.comments; a not_found response means the post did not resolve for this lookup.
Each comment has text and nested replies.items. Walk those items if you need the replies already returned. For more top-level comments, pass data.page.nextCursor as cursor with the same post URL when data.page.hasMore is true. Each nested reply list has its own replies.page; pass that list's cursor to the same endpoint to continue it. Deduplicate comments by comment.id across returned pages. Stop at a page or credit budget, and record any reply lists left unread.
A top-level hasMore: false means that list has no next page. It does not mean every nested reply has been collected. See the comments reference.
Batch and dedupe
The same post can match several phrases. Keep one row per post.id and retain the queries that found it. Separate cross-posts have separate IDs and discussion URLs; deduplicating by ID or URL does not merge them into one discussion.
Save the following as reddit-research.mts. The .mts ending allows await outside a function even in a default Node project. This script searches two phrases, reads up to two pages per phrase, and writes author-free rows plus request records to JSON. It keeps the first observed metrics for a repeated post.
Install the dependencies in your project, set SOCIALFETCH_API_KEY, then run:
The output's searches tells you why each query stopped: complete, page_limit, error, or missing_or_repeated_cursor. Only complete means the API reported no next page for that query. The script makes at most four requests, costs up to 4 credits, and does not fetch scoped searches or comments. If a request fails, it writes partial output with errors and exits with a failure status. Inspect those errors before using the file.
Cursors are opaque. Reuse the exact returned value with the same query, sort and timeframe; do not build or decode one yourself. For a complete global-plus-scoped workflow with selected first-page comments, use the Reddit research recipe.
Store rows your PM can sort
Keep observations separate from the raw discussion. Add a research note only after reading the thread and comments.
| Column | Source | Purpose |
|---|---|---|
| Post ID and URL | post.id, post.url | Keep one discussion row and link back to evidence |
| Search matches | Script's foundBy | Explain why the discussion entered the sample |
| Published date | createdAt (feed: publishedAt) | Distinguish old discussions from recent ones |
| Captured date | Script's capturedAt | Record when metrics were observed |
| Engagement | Score and comment count for that endpoint | Decide which discussions to read next |
| Request audit | meta.requestId, meta.creditsCharged | Trace each request and total spending once per request |
| Theme and evidence note | Your reading of the discussion | Record the problem described, its context and a source URL |
Use null for an unknown count rather than treating it as zero. The script's separate requests list records charges once per request: do not sum a request's charge once for every post it returned.
Before sharing a spreadsheet or sending text to a summariser, remove author fields and inspect titles, bodies and comments for personal details. Omitting a username alone does not anonymise the text. Keep source URLs beside research notes so someone can check the context.
Troubleshooting
Empty results
Try a shorter phrase, a wider timeframe, or a relevant scoped search. Queries are limited to 512 characters. An empty result is not evidence that no one has the problem.
not_found
For subreddit lookups, check exact casing. For comments, pass the full post URL returned by search. The status alone does not establish whether content was deleted, made private or unavailable for another reason.
Duplicate rows
Deduplicate post IDs across queries and pages. Keep foundBy so removing repeated matches does not lose the query history. Cross-posts remain separate discussions.
lookup_failed or temporarily_unavailable
Keep error.requestId (SDK: result.error.requestId) and retry later. Honour Retry-After when present on a 503 response. These failures are not charged on the endpoints used here. Contact support with the request ID if the problem continues.
insufficient_credits
The request cannot proceed with the available credits. Check the error message and credits documentation. The example stops the affected query and records the error.
Billing and boundaries
Each completed global search page, scoped search page, subreddit lookup, feed page and comment page costs 1 credit. Completed empty results and not_found lookups are charged. Another page or nested reply request costs another credit. Deduplication does not refund earlier searches. Check meta.creditsCharged for the actual charge.
The three Playground requests above cost 3 credits if they complete. Running the batch script separately costs up to 4 more. Invalid inputs rejected before lookup, lookup_failed and 503 temporarily_unavailable are not charged on these routes.
Search results reflect the queries, communities and windows you chose. Counts are observations at capture time. They do not establish market share, customer sentiment, willingness to pay or how common a feature request is. Use public data under the Terms.
What you can build
Use the evidence rows for a competitor comparison, a list of feature requests to investigate, or a review of discussions after a release. For repeated runs, keep the query settings and capture dates, deduplicate post IDs within each run, and retain history if you want to compare observations. See social listening for the wider workflow.
FAQ
Can I search all of Reddit at once?
Global search finds public posts across communities. Treat it as a search result, not an exhaustive census of Reddit or your customers.
How do I scope to one community?
Use Subreddit Search with both subreddit and query. Copy the community name's exact casing, such as ObsidianMD.
Why did my subreddit lookup return not_found?
Check exact casing first. The status means the lookup did not resolve; it does not establish why the content is unavailable.
Are empty search results charged?
Yes. Completed empty searches and not_found lookups cost 1 credit. Check meta.creditsCharged.
How much does this example cost?
The batch script makes at most four search requests, costing up to 4 credits. The three separate Playground requests cost 1 credit each on completion. Extra pages and comment requests cost another credit each.