Collect comments on a public post, save where and when they came from, then analyse the text. This guide uses YouTube for a complete first collection and explains the differences for other platforms.
You need a Social Fetch account with credits, a public video URL and, for the script, Node.js and an API key. The Playground uses your signed-in workspace; the script authenticates with a secret key. Keep that key on your server, outside source control and browser code.
A comment is an observation. A sentiment label is an interpretation of that text. Neither a page of comments nor a model's labels tell you what all viewers, customers or unique people think.
Test a comment request
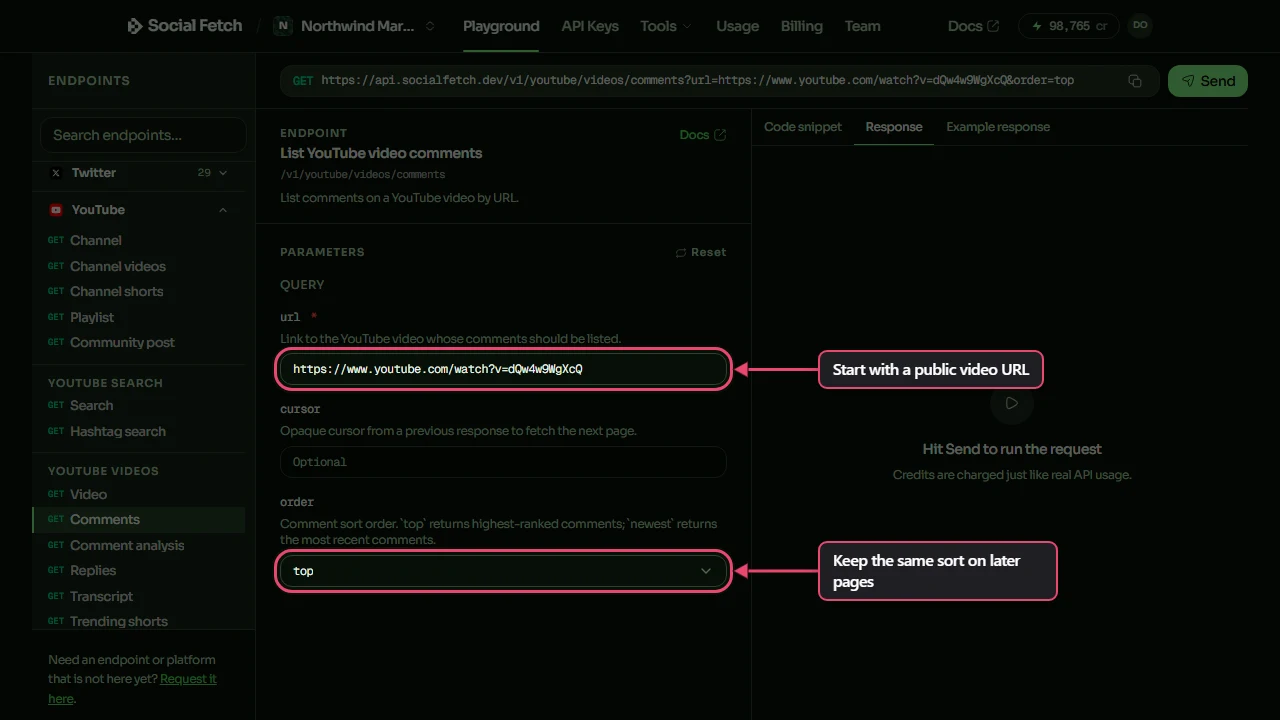
- Open the Playground. Choose List YouTube video comments under YouTube if it is not already selected.
- In url, paste the public video's full watch URL. Set order to top for ranked comments or newest for recent comments. Leave cursor empty for the first page.
- Click Send. This performs a billed lookup. Use the Response tab for the result; Example response shows sample data instead of a new lookup.
To make the same request from a terminal, set SOCIALFETCH_API_KEY privately in your environment, then run:
Use your own target URL for research. The example video demonstrates collection only; this guide does not calculate sentiment results for it.
Read comments and replies
In a successful comments response, data.lookupStatus says whether the video was resolved. found can accompany an empty data.comments array. It does not prove that every comment is available.
| YouTube comment field | How to use it |
|---|---|
id, text | Keep the ID for deduplication and use the text as analysis input. |
createdAt | Comment publication time; keep your collection time separately. |
likeCount, replyCount | Observed engagement counts, not sentiment or a count of unique people. |
author.creator | Whether the comment is from the video's creator. Decide whether to analyse creator comments separately. |
repliesCursor | A separate thread's starting cursor. null means no cursor is available. |
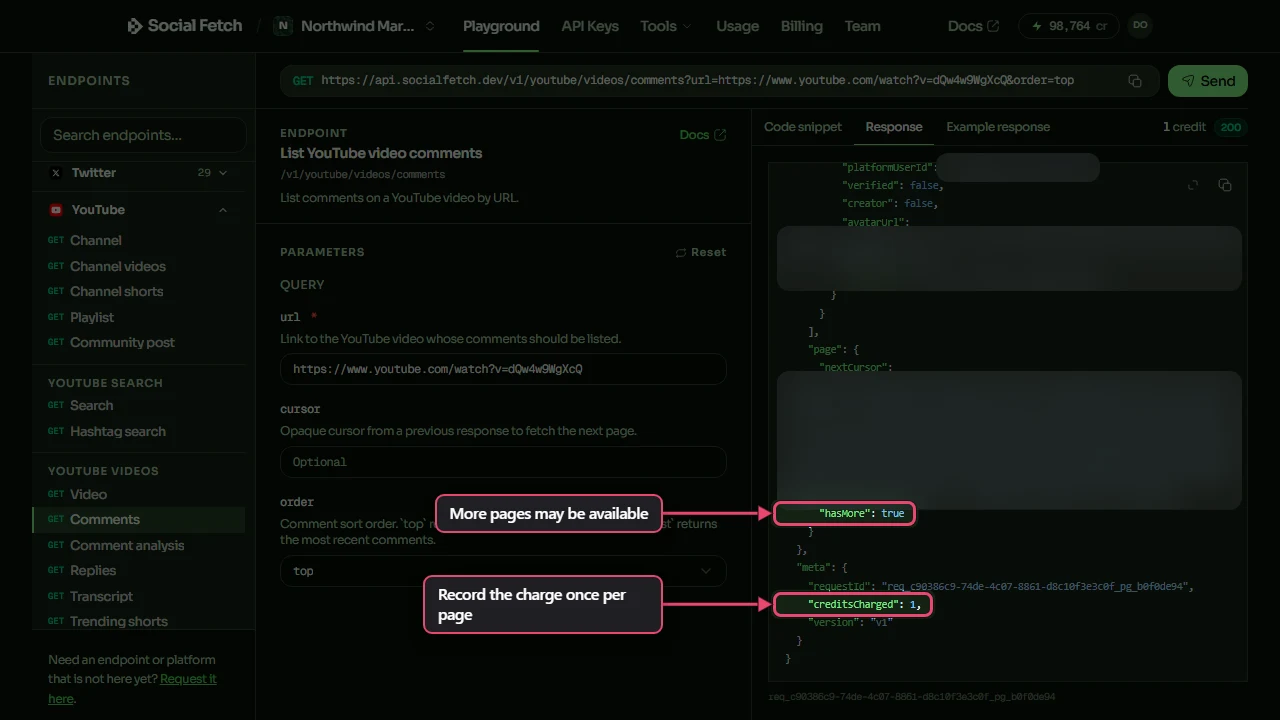
data.page.hasMore, data.page.nextCursor | Whether another top-level page is available and its opaque continuation token. |
meta.requestId, meta.creditsCharged | Save once per page for support and cost accounting. |
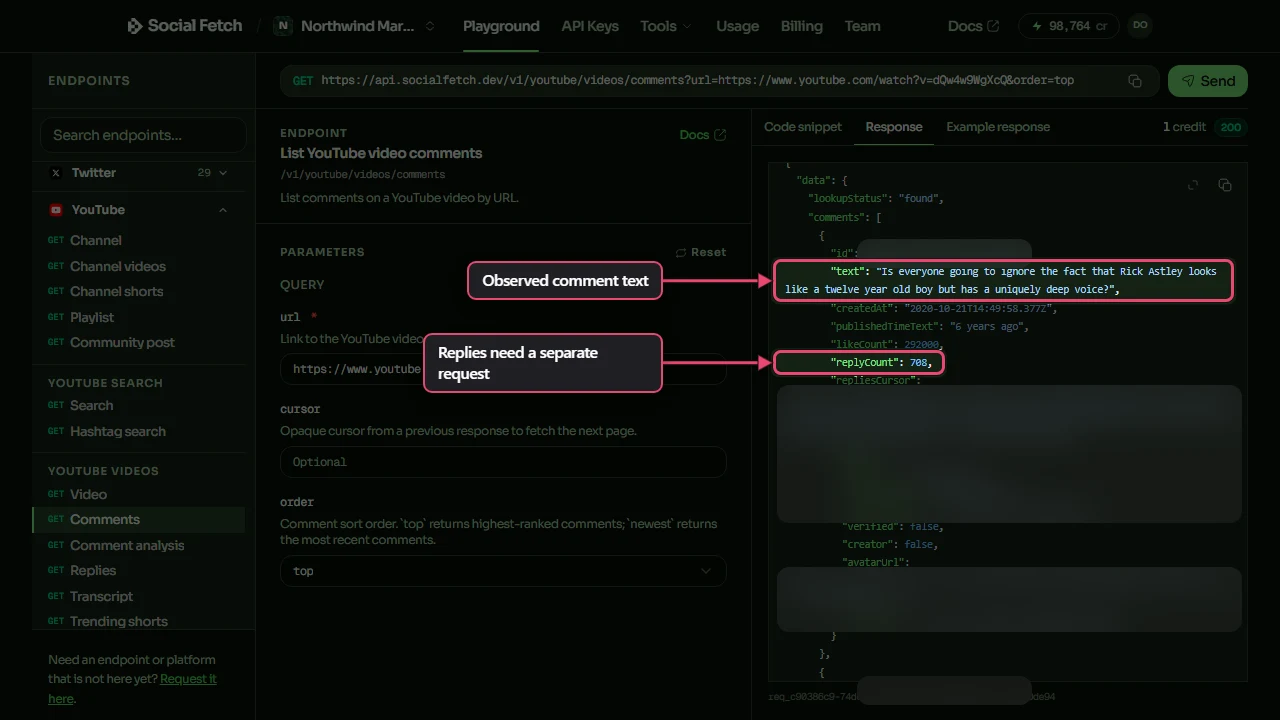
Replies need their own request. Copy a comment's non-null repliesCursor, then pass it as cursor:
Set REPLIES_CURSOR to the exact returned value. Do not decode, edit or build a cursor yourself. For subsequent reply pages, use the reply response's data.page.nextCursor. Its rows are in data.replies, with likes, nullable publishedAt, and author.isCreator. There is no lookupStatus on this replies response. The SDK method is client.youtube.getVideoCommentReplies({ cursor }).
Keep the parent comment ID and source video URL alongside each reply. A positive reply to a negative comment may be agreeing with the complaint. Read the parent before assigning a label.
References: YouTube comments and YouTube replies.
Collect a bounded sample
Choose a page budget before running a loop. The script below collects at most three top-level pages for one video and saves each completed page immediately. It does not fetch replies. Reducing maxPages reduces the maximum number of requests.
- Open API keys. If you need a new key, enter a Name, choose an Expires value, then click Create key.
- In Save your API key, copy the Secret into your private environment as
SOCIALFETCH_API_KEY, then click Done. The full secret is shown only once. - Create a directory, run
npm init -y, thennpm install @socialfetch/sdk tsx. - Save this code as
comments.mtsin that directory. The.mtsextension lets the script use top-levelawait. - Run
npx tsx comments.mts.
Each file records the source, sort order, collection time, pagination state and request metadata. A later failure leaves earlier page files intact. Deduplication here applies within a run; when combining runs, upsert on platform, source URL and comment ID while keeping dated observations. Repeated text with different IDs is not proof of a duplicate person.
Keep these files private: comment text can contain names, contact details or quoted handles, and comment IDs can lead back to people. Remove personal information before sharing analysis or sending text to a classifier. Set a retention period and restrict who can read the raw collection.
null means unavailable, not zero, false or neutral. Keep it when mapping other platforms' fields. Count empty text separately and exclude it from text classification; an Instagram GIF-only comment can have empty text.
Use another platform
Use the same collection plan, with the platform's own query and response fields. Follow its reference rather than copying YouTube's sort parameter to every endpoint.
| Platform | Request and important differences |
|---|---|
| TikTok | GET /v1/tiktok/videos/comments with url, optional cursor and trim. Rows use text, likes, replyCount and language. totalComments can be null and does not prove complete coverage. |
GET /v2/instagram/media/{media}/comments with sort=top or newest and optional cursor. Put a shortcode in {media}, or encode the media URL as one path segment. Counts and author can be null. Keep the same media and sort throughout a cursor chain. | |
GET /v1/reddit/posts/comments with url, optional cursor and trim. Rows use text, nullable score, parentId and isSubmitter. Walk replies.items recursively; each replies object also has its own page. Flattening the returned tree does not fetch missing reply pages. | |
GET /v1/facebook/posts/comments with url or feedbackId, and optional cursor. Rows use text, reactionCount and repliesCursor. | |
| Rumble | GET /v1/rumble/videos/comments with url. This query does not accept a cursor; do not assume every comments endpoint supports pagination. Engagement counts can be null. |
For Instagram replies, use the comment replies route with both media and comment ID. The SDK methods are client.instagram.listMediaCommentsV2 and client.instagram.listCommentRepliesV2. Use Facebook's replies route for its reply cursors.
Add sentiment labels
Choose the question first: sentiment about the video, the product, delivery or something else? A comment can praise the video while criticising the product. Write a short labelling rubric for that target, including how to handle mixed opinions, questions, sarcasm, emoji and insufficient context.
Start by reading a sample yourself. A keyword such as "refund" can find text to review; its presence alone does not establish negative sentiment. If you use a classifier, send redacted text with an internal row reference and only the context it needs. Treat comments as quoted data, never as instructions to the model.
Save analysis separately from collected fields. Record the input snapshot, rubric or prompt version, model and version, run time, label and review status. Allow an uncertain or unclassifiable outcome. Keep human corrections, and evaluate a fixed, manually labelled set before comparing model versions. This guide does not run a classifier or publish model-generated labels.
Report coverage honestly
Describe a result as "sentiment among the collected, classifiable comments", and state its denominator. Report the number of distinct comment IDs collected, how many had usable text, how many were classified and how many remained uncertain. A row count is not a unique-person count; one account can comment repeatedly and one person can use several accounts.
Record the target posts, collection dates, sort order, page budget, whether replies were included and why collection stopped. end_of_available_pages means the cursor chain ended for that lookup, not that you recovered deleted, hidden or otherwise unavailable comments. A reported total comment count can cover a different scope from the rows returned.
Ranked pages favour visible comments; newest pages favour recent ones. Neither is a random population sample. If you compare top and newest collections, keep them as separate collections and deduplicate overlap before a combined count. Filtering on likes or weighting by engagement changes the question to sentiment among selected or weighted comments. Likes are not independent votes on a sentiment label.
For comparisons, keep the target, sort, reply policy and classifier method consistent. Do not project percentages from these comments onto all viewers or customers, or call a change in two differently collected samples a population trend.
Costs and troubleshooting
A completed YouTube comments request costs 1 credit per page. A completed reply request also costs 1 credit per page. The script's three-page budget therefore allows up to three credits, with no replies. Re-running it starts a new billed collection. Completed empty pages and not_found comments lookups are billed; check meta.creditsCharged and the request log. See credits and pricing before scaling to many posts.
found with no comments: keep the empty result as an observation. It does not explain whether comments were disabled, removed or unavailable. Do not classify it as neutral sentiment.
not_found: check the full public post URL and access in the platform's browser view. The response alone does not establish why the source was unavailable.
hasMore: true with a null or repeated cursor: stop and save the request ID. Keep your partial sample and its stop reason. Do not loop on the same token or claim that collection finished.
unauthorized / HTTP 401: check that your environment contains an active API key and that you sent it in x-api-key. Signing into the dashboard does not authenticate a terminal request.
insufficient_credits / HTTP 402: stop collection and check the workspace balance. Do not repeatedly retry a billing refusal.
lookup_failed or HTTP 503: preserve the error code and request ID. Check Retry-After when supplied, then retry within a bounded budget. A response lost to a network error leaves its billing outcome uncertain; check the request log before replaying it. The example script stops on errors rather than retrying automatically.
Replies missing from the analysis: YouTube top-level pagination never fetches reply threads. Reddit's returned nested replies may also have further cursors. Record whether those pages were collected.