Get spoken text from a public video, then store it for search, summaries or quote checking. The response format depends on where the words came from: a caption track can contain timings; AI speech transcription here returns untimed text.
For a single video you don't need a key: paste the link into the free TikTok transcript generator or YouTube transcript generator.
For the API steps below, you'll need an API key. Try the requests in the Playground, or use the TypeScript SDK. The Quickstart explains authentication.
Choose a transcript source
| Source | Request | Where the words are | Timings |
|---|---|---|---|
| YouTube captions | GET /v1/youtube/videos/transcript?url=… | data.transcript.plainText | segments with startMs and endMs |
| TikTok captions | GET /v1/tiktok/videos/transcript?url=… | data.transcript.content, format: "webvtt" | WebVTT cues |
| TikTok AI speech | Same route, useAiFallback=true when captions are absent | data.transcript.content, format: "text" | None |
| Instagram speech | GET /v2/instagram/media/{media}/transcript | data.transcript.text | segments: null |
All return { data, meta }. Keep meta.requestId for support and meta.creditsCharged for your spending record. Check the transcript itself as well as data.lookupStatus: found can still mean there is no text.
Get a YouTube transcript
- Open the Playground and choose Transcript under YouTube videos.
- Paste
https://www.youtube.com/watch?v=arj7oStGLkUinto url. - Click Send and read the Response tab.
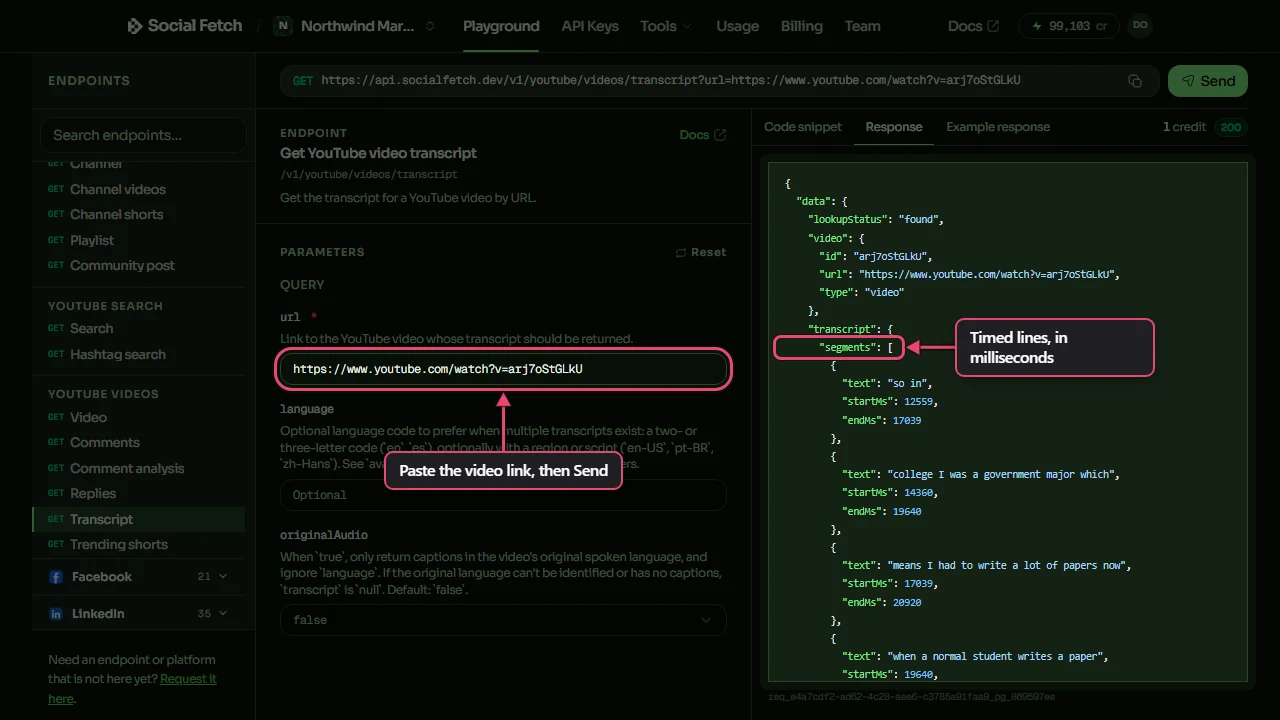
The same request over HTTP:
The saved real response starts with this segment (an excerpt, not the full response):
Caption segments can overlap and break mid-sentence. Keep them for timestamped citations; use plainText for reading and search. YouTube can resolve the video with lookupStatus: "found" and transcript: null. No readable captions means no text and no charge. This endpoint has no AI fallback flag.
Reference: YouTube transcript.
Choose a language and caption source
YouTube returns availableLanguages: each track has a code, a nullable name, and autoGenerated. Pass a listed code as language, for example es. YouTube accepts two- or three-letter codes and region or script tags such as pt-BR and zh-Hans.
- Set language to
esfor the TED example. - Click Send.
- Compare
transcript.languageCodewith the requested code and inspectavailableLanguages.
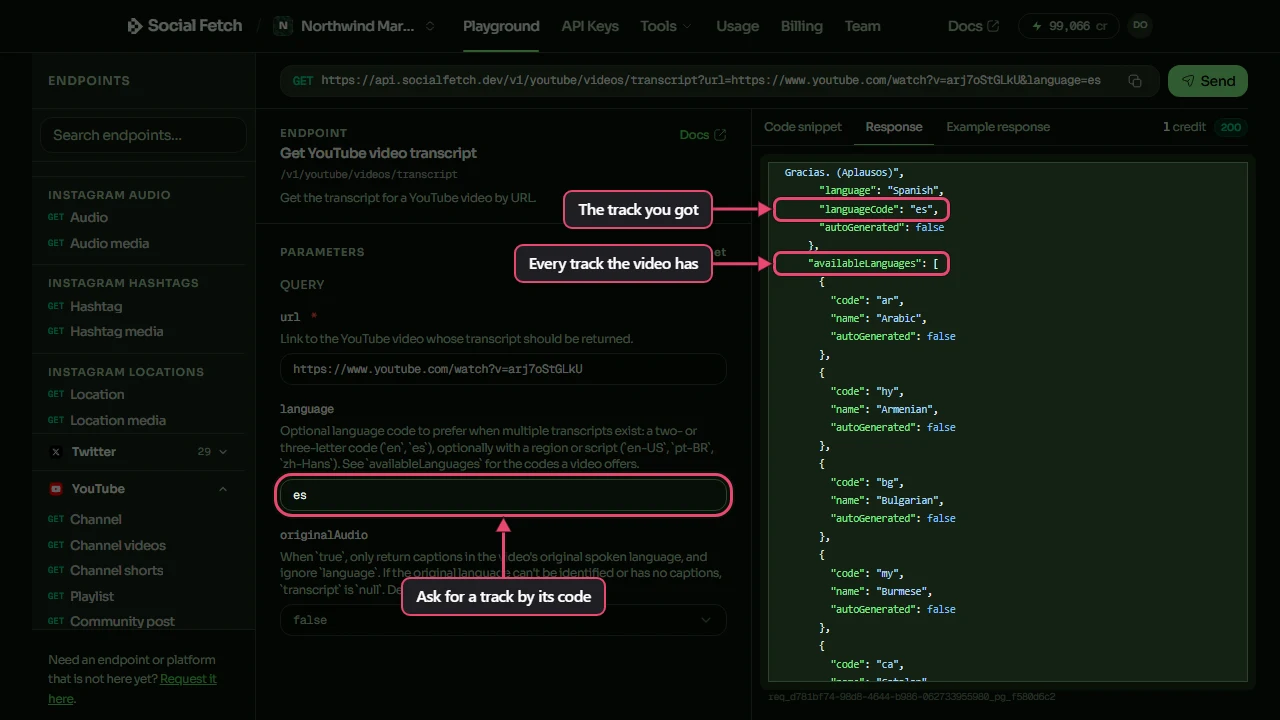
transcript.language is a readable label; languageCode identifies the returned track when known. transcript.autoGenerated is true for automatic captions, false for creator-uploaded captions, or null when the source cannot be identified reliably. A null source does not mean manual captions. There is no manual-only switch.
Set originalAudio to true to restrict captions to the original spoken language; this ignores language. If that language cannot be identified or has no captions, transcript is null.
An unavailable language does not guarantee a substitute track. Our real request for language=sw on this video returned found, transcript: null, and creditsCharged: 0, with other tracks still listed. Choose an available code or omit the preference and inspect what comes back.
TikTok accepts an optional two-letter language code when available. Its transcript payload has no returned language or caption-source field, so keep the requested language separately and verify the words. Neither this option nor YouTube's language selection promises translation. Instagram has no language parameter; its returned language is null.
Get TikTok captions or AI text
-
Choose Transcript under TikTok videos in the Playground.
-
Set url to:
Request -
Leave useAiFallback false and click Send.
This captioned Duolingo video returned format: "webvtt". The start of its real content value is:
When there is no caption track
Try this URL with useAiFallback false:
In our capture, the video resolved as found but transcript was null. A completed empty TikTok lookup still costs 1 credit; not_found is not the only possible empty state.
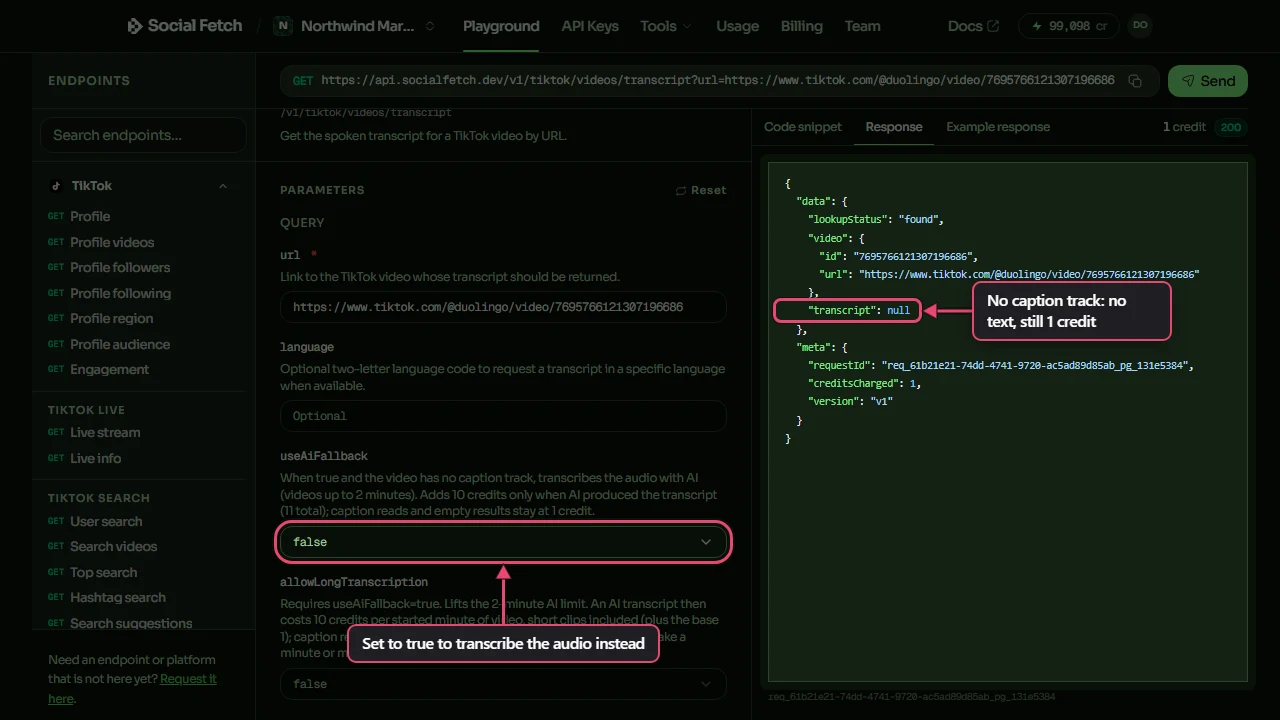
- Set useAiFallback to
true. - Click Send to request AI speech transcription when captions are absent.
- Read
transcript.formatbefore parsingcontent.
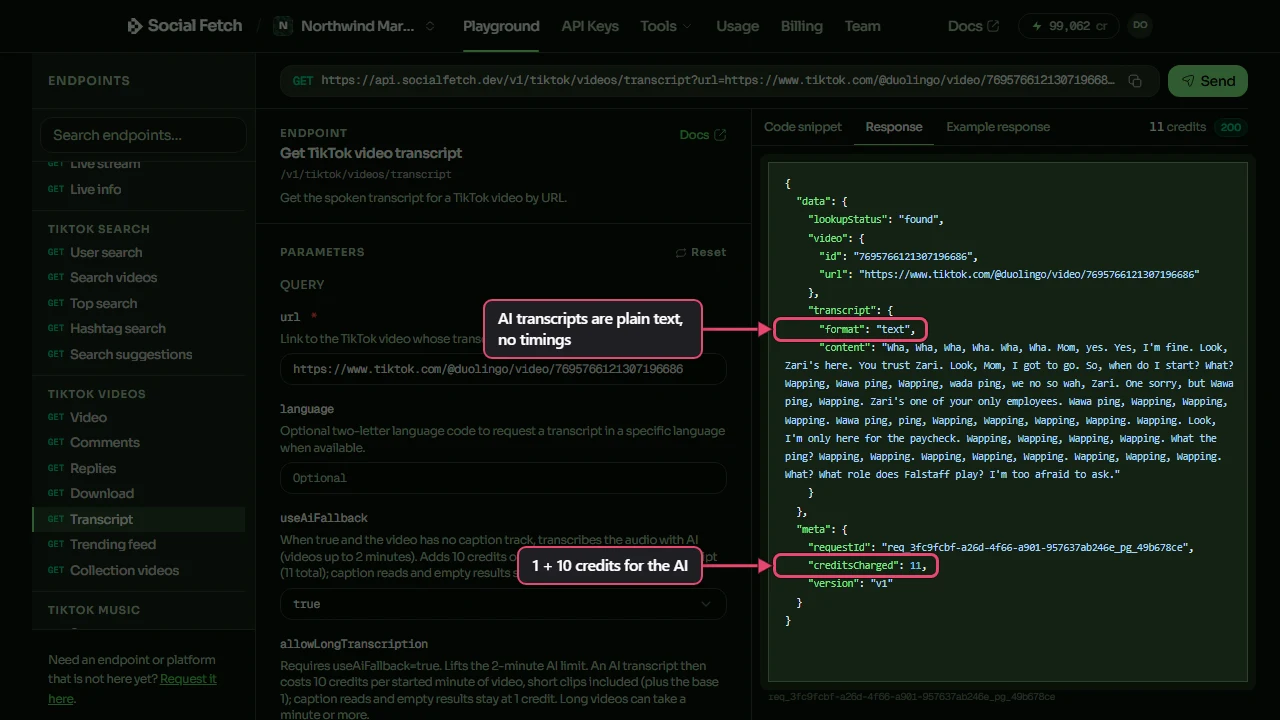
Fallback does not guarantee speech or a usable transcript. It also does not force AI when captions exist. Existing captions remain WebVTT and cost 1 credit even with the flag enabled. AI text can mishear names and speech; check quotes against the video. See the TikTok transcript guide and endpoint reference.
Get Instagram Reel speech
- Choose Media transcript under Instagram media.
- Set media to the public Duolingo Reel shortcode
DKuRMDEsbYB. - Leave allowLongTranscription false and click Send.
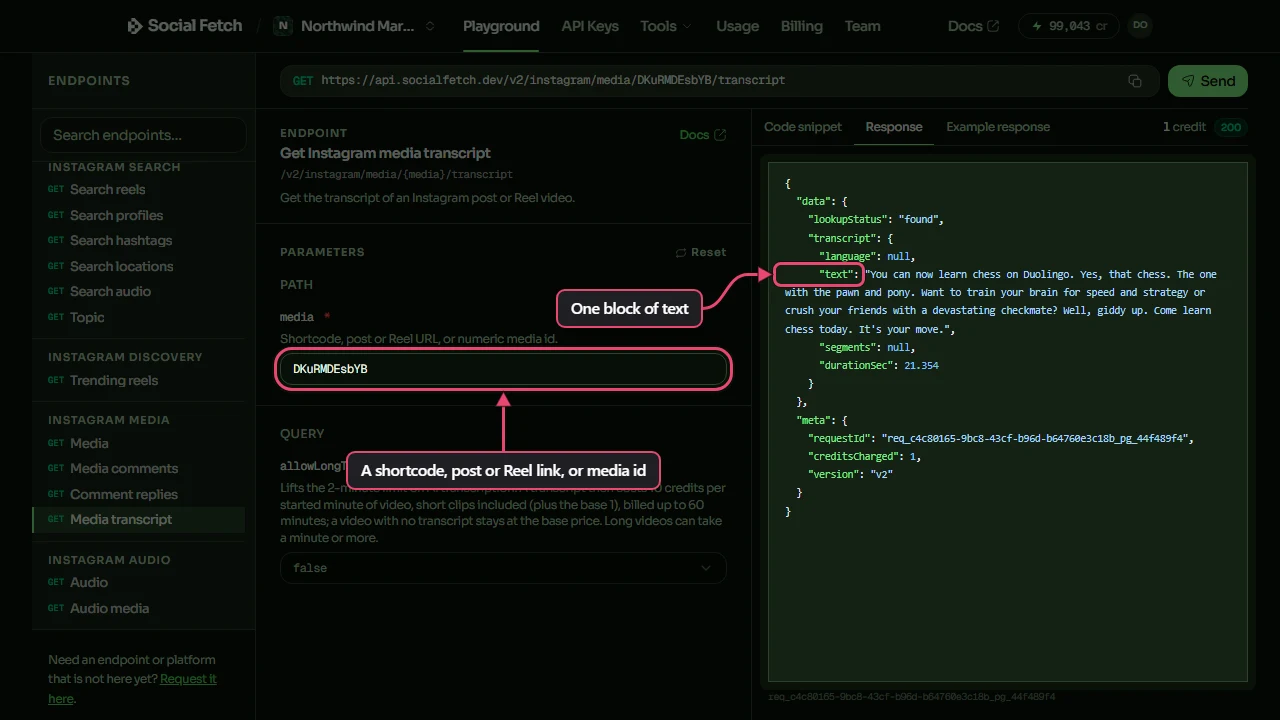
Instagram accepts a shortcode, a post or Reel URL, or a numeric media id in the path. URL-encode a full URL used as a path value. Share links are rejected. Speech transcription up to 120 seconds is included in the 1-credit default lookup; there is no useAiFallback switch.
found with transcript.text: null means no speech was detected. not_found with transcript: null means the post is missing, private or has no video. Both completed outcomes cost 1 credit. Video carousels join the available texts in order, separated by blank lines. See the Instagram transcript reference.
Set a transcription budget
| Mode | Actual charge for a completed lookup | Credits needed for preflight |
|---|---|---|
| YouTube | 1 with transcript; 0 when transcript is null | 1 |
| TikTok, captions only | 1, including empty results | 1 |
TikTok, standard useAiFallback=true | 11 when AI produces text; 1 for captions or empty results | 11 |
| Instagram, default | 1, including short AI transcription and empty results | 1 |
| TikTok or Instagram, long AI mode | 1 + 10 per started minute when AI produces a transcript, capped at 601; captions or empty results stay at 1 | 601 |
The default AI limit is 120 seconds. To lift it on TikTok, send both useAiFallback=true and allowLongTranscription=true. The SDK's client.tiktok.getVideoTranscript() forwards both options.
For Instagram, send allowLongTranscription=true over HTTP. The current SDK's getMediaTranscriptV2() sends only the media path and does not forward this query option. Replace the shortcode below with the video you intend to transcribe:
Long mode changes the price even for short AI clips: a 90-second transcript costs 21 credits. The maximum billed duration is 60 minutes, so have 601 credits available for preflight even when you expect a smaller actual charge. This is a billing cap, not a guarantee that every long video can be transcribed. YouTube caption reads do not use these AI flags or this per-minute price.
Cap the number of URLs and paid attempts before a batch. A second request with different flags is another lookup. Avoid automatic AI retries for every empty caption result; select which clips justify the cost. Keep a credit ceiling separate from concurrency, and record actual charges from every completed response. Details: Credits and billing.
Store one document shape
Keep plain text for search and the original transcript for timings or later checks. This visual uses excerpts from our saved real responses; the text from different videos remains separate.
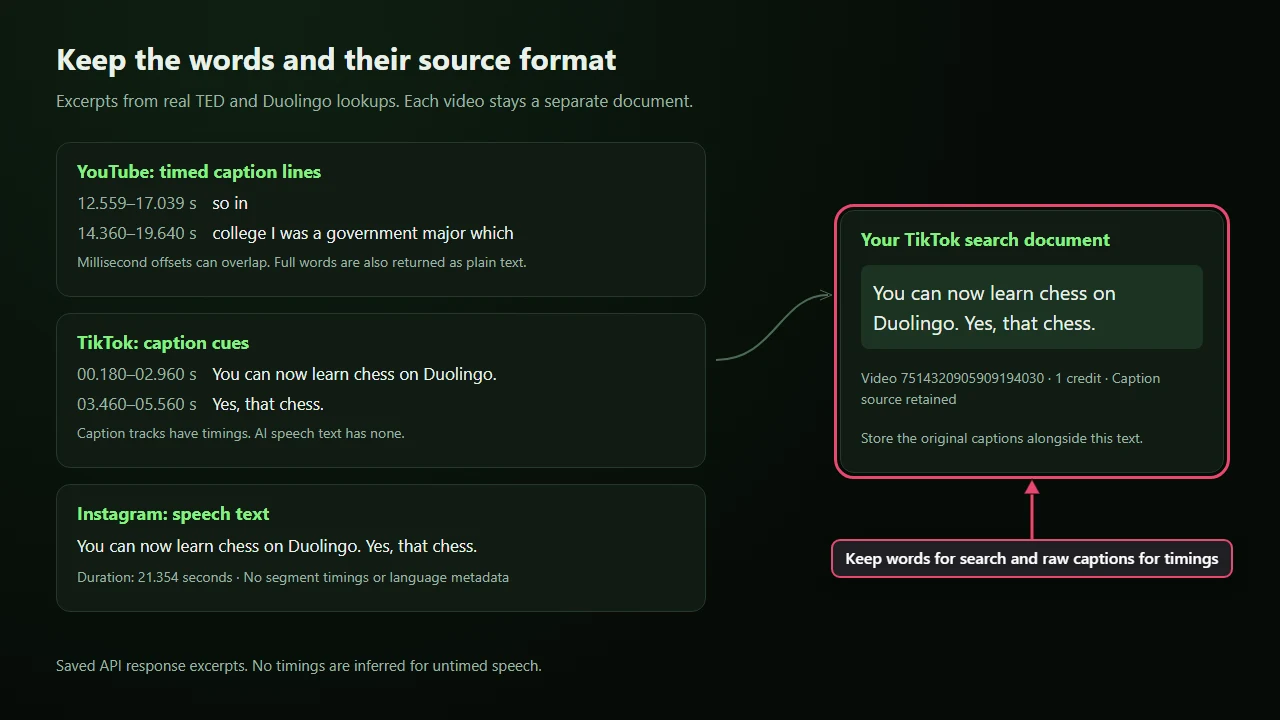
Install @socialfetch/sdk, save the following as transcripts.mts, and run npx tsx transcripts.mts. The .mts extension enables the top-level await even in a project without "type": "module". Set SOCIALFETCH_API_KEY in your environment first. The example makes three lookups with concurrency two, at most 3 credits in this default mode. TikTok AI is off; Instagram uses its default short-video mode. It prints empty outcomes too, so charges are not lost when text is absent.
The WebVTT extractor is a small cue-text helper, not a subtitle renderer: it strips cue tags, preserves text entities, and keeps neither cue settings nor timings in plainText. Use a WebVTT parser if you need to edit or render subtitles. Never apply it to TikTok format: "text". Instagram has no segment timestamps to recover.
For retrieval, split long text into chunks that fit your embedding model. Attach the source URL and request id to each chunk. Preserve YouTube segments and TikTok WebVTT separately if you need timestamped links; do not invent timings for AI text. For summaries, check the model's context limit before sending a whole long transcript. The video transcription recipe goes further with a reusable pipeline.
Troubleshooting
HTTP 200 but no text
Read both lookupStatus and the nullable transcript fields. YouTube null transcripts are free; completed empty TikTok and Instagram results cost 1 credit. Save the request id before filtering empty documents out of a search index.
video_too_long_for_transcription
The default AI duration limit was exceeded. Decide whether to opt into long mode and its price, then send the appropriate flags above. Retrying the same default request will not lift the limit.
The language is wrong or missing
On YouTube, inspect availableLanguages, languageCode and originalAudio. On TikTok, the two-letter preference only applies when available; the response has no language confirmation. Instagram returns null language metadata. Do not label a document with the requested language as though it had been detected.
lookup_failed or temporarily_unavailable
The lookup could not complete. These failures are not charged. YouTube can also return a lookup_failed data outcome without a transcript, which is free. Inspect the error or data outcome, keep its request id, and respect Retry-After when present. Use bounded retries for temporary failures; contact support if they persist.