Build a dashboard that answers two questions: which public posts matched your brand searches, and which IDs appeared since your previous checks? This guide collects TikTok, X, YouTube and Reddit results, then stores them in Postgres.
You need a Social Fetch API key, Node.js for the TypeScript SDK, a database and a scheduled worker. Start with the brand monitoring recipe to try the searches before writing storage code.
Search results are a sample of what your queries found. First-seen posts are not everything published about a brand. Treat the first successful poll as a baseline rather than sending spike alerts for all its results.
For scheduled alerts without a database, use Monitors. Search monitors record a baseline on the first successful check and send new matching posts on later checks. Creating one requires a workspace with a previous payment. Each successful check, including the baseline, costs the source's normal API price. Monitors do not calculate the custom dashboard metrics below.
Try one search
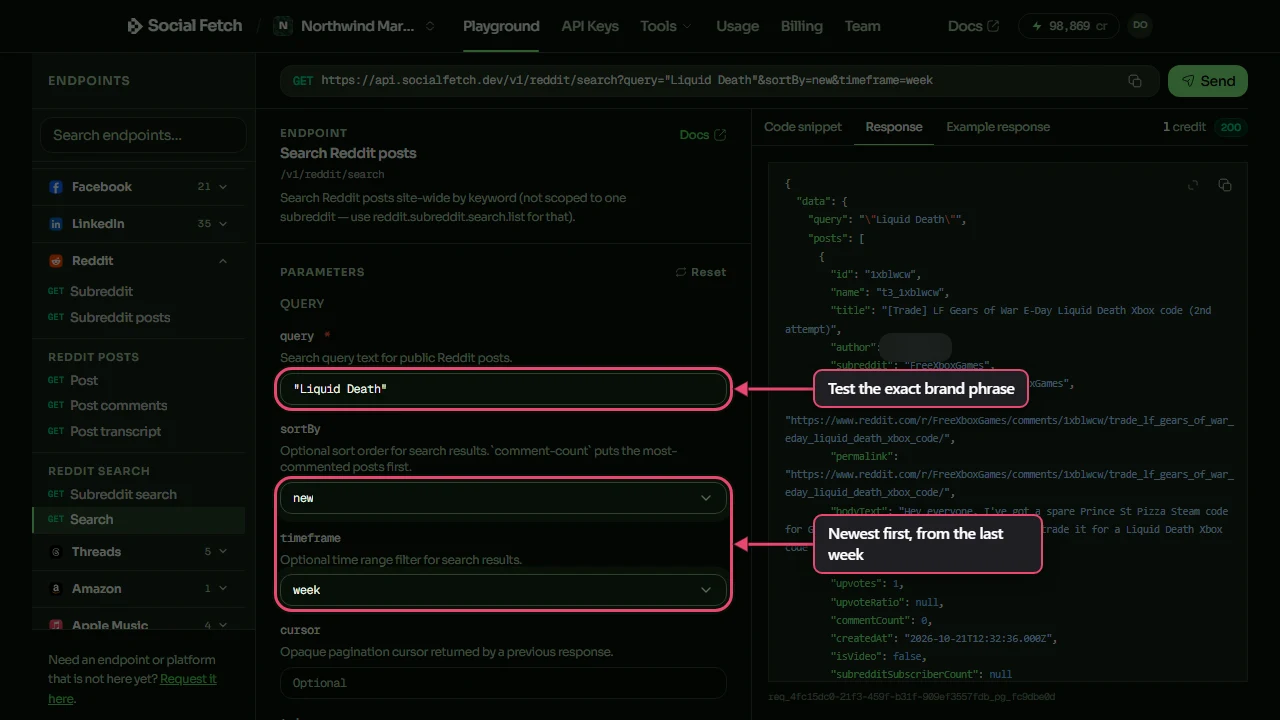
- Open the Playground and choose Search Reddit posts.
- Set query to
"Liquid Death", sortBy tonew, and timeframe toweek. Liquid Death is the public brand used in the saved examples. - Click Send. Check the returned posts and credit charge before scheduling more calls.
Keep a watch list with a separate entry for each platform and query. Store its exact filters and schedule so you can explain later changes in results. Start with one brand term, then test misspellings and competitor terms before adding them.
For X, put operators inside query. For example, "Liquid Death" lang:en min_faves:5 asks for English posts with at least five likes. since:YYYY-MM-DD and until:YYYY-MM-DD can bound an incident window. The advanced search builder compiles these filters for you. The SDK accepts query, section, limit and cursor; do not pass language or minLikes as separate options. Avoid engagement thresholds when you want to find complaints before they attract likes.
Collect a poll with the SDK
Install the SDK in your worker project:
Set SOCIALFETCH_API_KEY in your worker's environment. Keep it on the server, outside browser code and source control.
This example fetches one page per platform and maps the different result fields to a small common row. YouTube's upload filter is this_week; TikTok's date filter is this-week.
Call poll for each due watch term. Save each successful poll before moving to the next platform, and record failures separately. A failed Reddit request should not discard successful X results.
To collect more pages, pass that platform's data.page.nextCursor back as cursor with the same query and filters. Stop when hasMore is false, the cursor is missing, or you reach your page budget. Each completed page is another billed request. A later scheduled poll starts a fresh search; an old cursor is not a freshness checkpoint.
References: TikTok search, X search, YouTube search, Reddit search.
Store posts and query matches
Keep one post row per (platform, post_id), plus one match row per watch term and post. A post matching both a brand term and a campaign term belongs to both watch lists. Putting only one watch_term_id on the post would lose that relationship.
This schema is a starting point for your own database:
For each successful poll, use one database transaction:
- Lock its
watch_termsrow so overlapping runs cannot both establish the baseline. - Insert
poll_runsusingmeta.requestId. If that request is already stored, stop this ingestion attempt. - Upsert
mentionson(platform, post_id). Update text andlast_seen_at, preservingfirst_seen_at. - Upsert
term_matcheson(watch_term_id, platform, post_id). For an existing match, update onlylast_seen_at. New matches use the poll's capture time; setis_baselineto true if this watch term has no completed baseline. - Mark
baseline_completed_atafter the first successful poll, even if it returned no posts. Commit before sending alerts.
Retrying ingestion of a saved response is different from making a new API request: the new request can cost credits even when it returns IDs you already stored. If the initial baseline includes several pages, finish that collection before marking the baseline complete. Store query options alongside the watch term and treat a changed query as a new watch term with its own baseline.
Store publication time separately from first-seen time. Search can surface an older post for the first time today. YouTube search dates can be approximate; do not make claims about exact publication minutes from them. A post disappearing from search does not prove it was deleted.
Read the dashboard
This custom dashboard visual uses the brand monitoring recipe's real saved responses. It is not a built-in Social Fetch dashboard. The second poll found 72 results; 12 platform/post-ID pairs had not been seen in the earlier poll. It collected only the first page of each search.
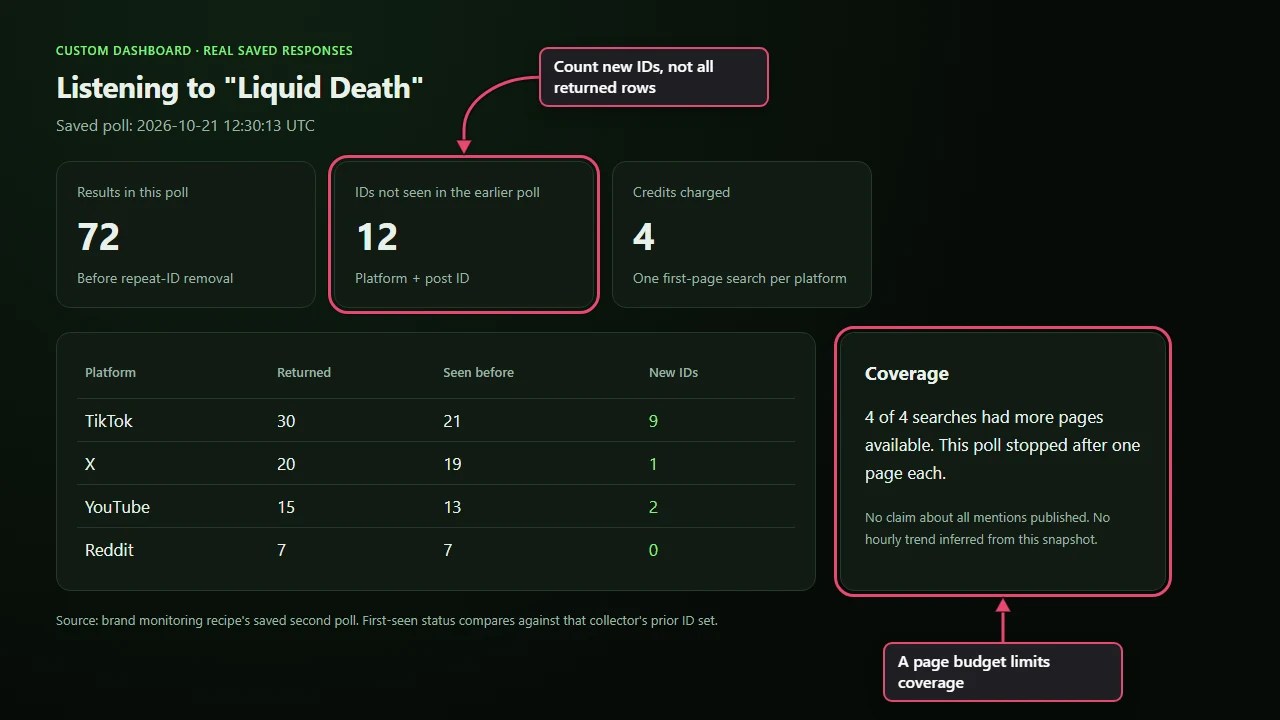
Count unique platform/post-ID pairs across a group of terms. Do not add per-term counts together: the same post can match several queries. For a per-term chart, use term_matches.first_seen_at; for a global chart, use mentions.first_seen_at. Exclude baseline rows from alerts and mark the initial collection on your chart.
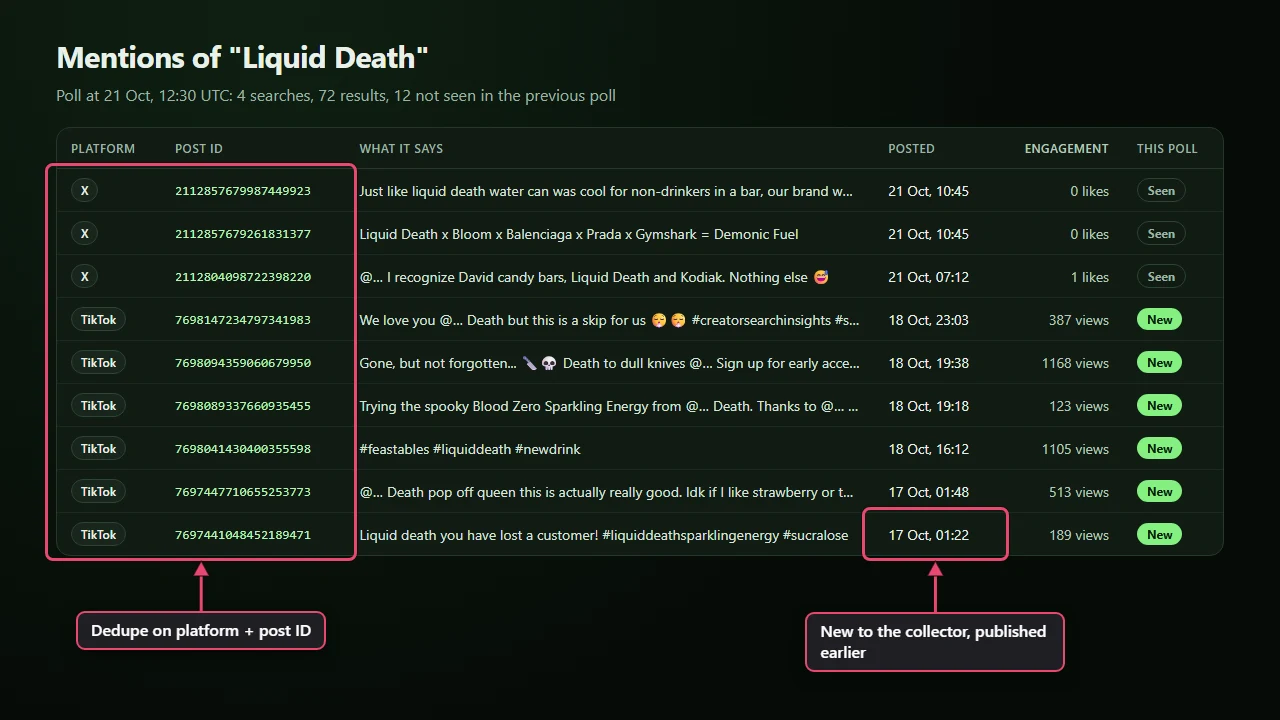
Keep the request log, credits and pagination coverage beside your chart. A successful empty search is a measured zero; a failed or skipped search is missing data. Show that gap rather than drawing a zero.
Check for spikes
Compare like with like. This SQL counts the most recent completed UTC hour and compares it with the preceding seven days of completed hours for watch term 1. It includes quiet hours as zero and excludes baseline posts.
Only run it after a full baseline period with successful collection in every hour being compared. Check poll_runs for coverage first. If an hour lacks a successful poll, defer the alert or explicitly model missing coverage. Filling a failed hour with zero would make the baseline misleading.
The multiplier and minimum of ten are example thresholds, not measured properties of the brand. Tune them after reviewing your results. Keep an alert record keyed by watch term and hour so repeated runs do not send the same alert twice.
Send a short alert with the watch term, measured window, count, baseline and links to the posts behind it. Keep post URLs when extending the ingestion mapping if you need clickable alert citations. To chart the hourly counts against the baseline, point a BI tool such as Metabase or Looker Studio at term_matches.
Schedule and budget
Run the worker on a schedule you control. Avoid overlapping jobs for the same watch term. Record successes and failures, retry transient errors with backoff, and honour Retry-After when present. Treat validation and authentication errors as configuration problems rather than retrying them repeatedly.
Each completed search used here costs 1 credit, including an empty result. Budget by requests, including extra pages and manual tests:
| Example schedule | Requests | Credits |
|---|---|---|
| 3 terms on the platforms in this guide, one page each, hourly | 288 per day | 288 per day |
| 5 X terms, one page each, every 15 minutes | 480 per day | 480 per day |
| 10 Reddit terms, two pages each, one collection | 20 | 20 |
Use meta.creditsCharged for actual totals and the request log to inspect individual calls. Failed lookups are not charged. Paid API calls have no request quotas, but capacity errors can occur; start with a small batch. See Credits.
Troubleshooting
TypeScript rejects language, minLikes or uploadDate: "week"
Use X operators inside query, and uploadDate: "this_week" for YouTube. TikTok video search is client.tiktok.searchVideos, with sortBy: "date-posted" for date ordering. Copy parameters from each route's reference rather than sharing one parameter object across platforms.
The dashboard keeps counting the same posts
Count first-seen rows rather than results returned by each poll. Preserve first-seen timestamps on upsert, dedupe on platform and post ID, and keep each query match in its own join row.
A spike appears after adding a watch term
Treat that term's first successful poll as its baseline. Keep baseline rows out of spike counts. Check for query changes, failed collection windows and missing zero hours before changing the alert threshold.
Search is empty but a post is visible in a browser
Try a less restrictive query in the Playground. Search coverage and ranking can differ from a direct post lookup. Do not promise complete coverage from this collector.
lookup_failed or temporarily_unavailable
Record the error code and request ID. Retry transient failures with backoff and use Retry-After when supplied. Leave a collection gap visible if retries fail. Contact support with the request ID if it persists.
FAQ
Do I need to build a worker?
Use Monitors for scheduled search checks and signed webhook delivery. Build your own worker for custom storage, query groups or spike calculations.
Does new mean newly published?
No. A post can enter search results after publication. Count first-seen IDs separately from publication dates, and label each chart clearly.
Does an empty search cost credits?
A completed search costs its normal price even when it finds nothing. Failed lookups are not charged. Record meta.creditsCharged for each successful request.
Will this find every mention?
No. Search returns public results available for your query and filters. Rankings, coverage and your pagination budget affect what you collect.