If you run your own scraper, you maintain the code that loads pages and extracts data. With Social Fetch, you call documented endpoints and maintain the code that uses their responses. Both approaches need error handling, checks for missing fields and a decision about what data you should collect.
Start with the fields your project needs. Neither approach is useful if it returns a successful response without the information your application requires. This comparison does not include measured speed, reliability or cost benchmarks.
The work you own
A scraper might use a browser to load a public page, then read visible text or embedded data. Your code turns that into a record your application can use. A change to the page can require an extraction fix.
An API endpoint is a documented operation, such as looking up a TikTok profile by handle. Social Fetch handles extraction; your integration reads its public response contract.
| Work | Your own scraper | Social Fetch |
|---|---|---|
| Getting the fields | Choose a permitted source and write extraction code | Check that an endpoint returns the fields you need |
| Responding to page changes | Diagnose and repair your extraction | Handle API errors and report failed lookups with their request IDs |
| Data shape | Define and maintain your schema | Read the endpoint's documented schema and map it into your records |
| Missing data | Distinguish missing content from extraction failure | Check the endpoint's outcomes and nullable fields |
| Repeated collection | Build scheduling, retries and storage | Integrate requests or use a suitable documented monitor; manage downstream storage |
| Spending | Track hosting, any network costs and engineering work | Track endpoint credits, integration work and downstream costs |
A shared response envelope does not make every platform's fields identical. A profile, a channel and a search result each have their own schema. Matching handles across platforms also does not prove they belong to the same person; see cross-platform creator profiles.
Check the data before choosing
Write a short list of required fields, acceptable missing values and how recent the data must be. Include a known public account and any edge cases your project needs to handle.
- Open the API reference and find the endpoint for your task. For this example, use TikTok profile.
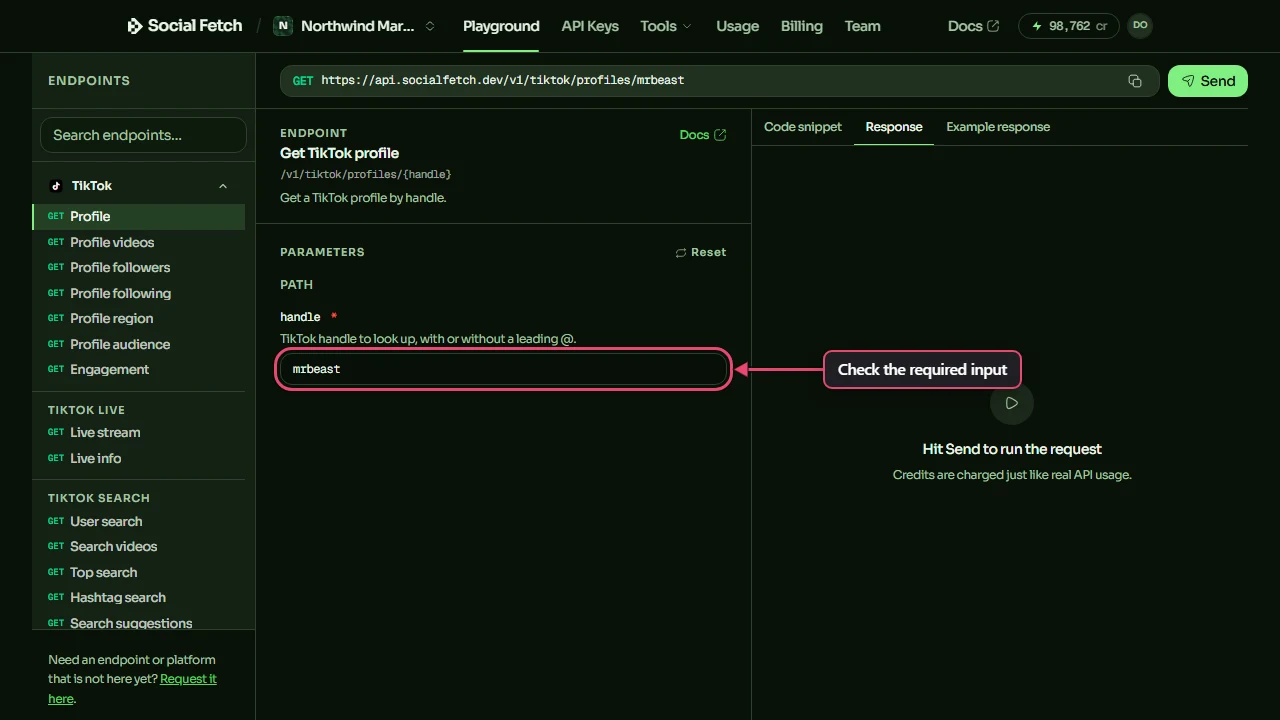
- Sign in to the Playground. Select TikTok and Profile if the endpoint is not already selected.
- Check the required handle input. Use
mrbeastfor the public example account.
- Read Example response to understand the documented shape. It is an example, not a new lookup or proof of current counts.
- Click Send when you want a live test. This spends credits. Compare the returned fields with your requirements, and keep
meta.requestIdandmeta.creditsChargedwith your test notes.
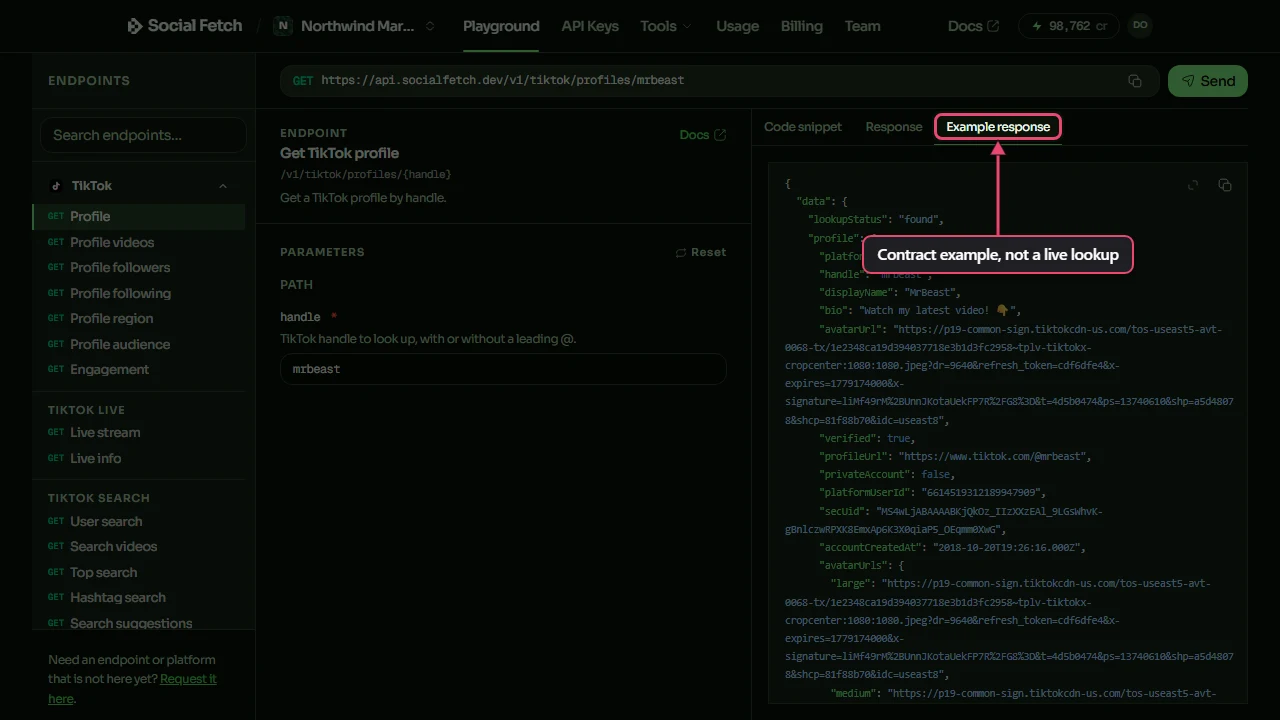
Every request is a live lookup, made when you call the endpoint. A screenshot or successful lookup does not establish complete coverage or a success rate for your workload.
Try the same lookup in code
Create a key on API keys, then set SOCIALFETCH_API_KEY in your environment. Keep the key on your server and out of source control. See the quickstart for setup.
This command uses a POSIX shell, such as Bash. It sends the key in x-api-key and prints HTTP headers as well as the response body:
For Node.js 18 or later, install the SDK:
Save this as profile.mjs and run node profile.mjs. The .mjs extension allows the import and top-level await, including in a project whose default is CommonJS.
The SDK returns ok: false for an API or client failure. A successful HTTP response can still describe a private or missing profile. Keep a missing follower count as null; replacing it with zero would turn unavailable data into a false measurement.
This profile endpoint returns one lookup, so it has no pagination cursor. List endpoints have their own pagination fields. Follow that endpoint's documented continuation value, keep the same search parameters, and budget for each additional request. Do not assume one request returns every result.
Outcomes, errors and billing
The TikTok profile endpoint costs one credit per completed lookup. A credit is a billing unit, not a fixed currency price; use Pricing for purchase options and the API reference for each operation's credit cost.
| Response for a metered lookup | What to do | Billing |
|---|---|---|
200, lookupStatus: "found" | Check that the needed fields are available | Completed lookup is charged |
200, lookupStatus: "private" or "not_found" | Record the outcome; do not invent missing values | Completed lookup is charged |
400 bad_request | Correct the input before trying again | Pre-lookup rejection is not charged |
401 unauthorized | Check the API key | Not charged |
402 insufficient_credits | Check workspace credits or the key's spend cap | Rejected lookup is not charged |
502 lookup_failed | Keep the request ID; retry with backoff if appropriate | Not charged |
503 temporarily_unavailable | Wait for Retry-After before retrying | Not charged |
These profile outcomes are not a universal list for every endpoint. Some list endpoints return an empty list without lookupStatus; some operations have special billing rules. Read Errors and outcomes and Credits alongside the endpoint reference. Cached completed results are charged in full.
Paid metered lookups with a valid key do not have a per-minute quota. Credits, key spend caps and service capacity still matter. Limit concurrency in your integration and handle temporary capacity errors; no quota does not mean unlimited simultaneous requests.
If a lookup fails repeatedly, contact support with its request ID and the operation you called. Do not send your API key.
Compare costs using your own measurements
Choose the same set of targets and required fields for both approaches. Decide what counts as a usable result before testing. Record missing or incorrect fields separately from transport failures, and keep retry attempts in the totals.
| Cost or measurement | DIY: record your value | API: record your value |
|---|---|---|
| Setup and integration | Build and test hours | Integration and test hours |
| Collection | Hosting and any network charges | Sum of meta.creditsCharged across requests and pages |
| Maintenance | Diagnosis, repairs and dependency work | Integration updates and diagnosis |
| Usable results | Records meeting your field requirements | Records meeting the same requirements |
| Failures and retries | Attempts, reasons and extra costs | Attempts, error codes and credits |
| Storage and handling | Retention, exports and access controls | Retention, exports and access controls |
Calculate cost per usable record from your total costs and usable record count. Keep engineering hours visible even if you do not assign them a money value. For API spending, use your actual credit purchase costs rather than assuming every endpoint costs one credit.
This guide supplies no proxy price ranges or sample annual savings. One successful test is also too small to establish production latency or reliability. If those affect your choice, measure a representative workload and record the test conditions.
Choose DIY, an API or both
DIY can fit a permitted one-off extraction, a learning project or a field absent from the API. It requires someone to own extraction and its failures. Check whether a platform's official API already covers your task before building a browser scraper.
Social Fetch can fit when its documented fields meet your needs and you want to delegate extraction maintenance. You still own validation of the returned data, your integration, storage and recovery from errors.
A mixed setup can use separate collection paths for different sources. Map both into one stored schema, record which path produced each record, and avoid silently overwriting a missing value with stale data from another path.
Public visibility does not settle what you may collect, store or use. Review applicable terms, including Social Fetch's terms, and get advice for your use case where needed. Using an API does not grant rights to content or remove your data-handling obligations.
Before choosing, confirm that you can answer these questions:
- Does the source return the exact fields you need, with acceptable missing values?
- Have you tested relevant outcomes rather than only a successful public profile?
- Who handles failures, changes and repeated collection?
- Does the measured total cost include integration, retries and maintenance?
- Are the intended collection, retention and use permitted?